Articles

Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler
AI Engineering

Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler

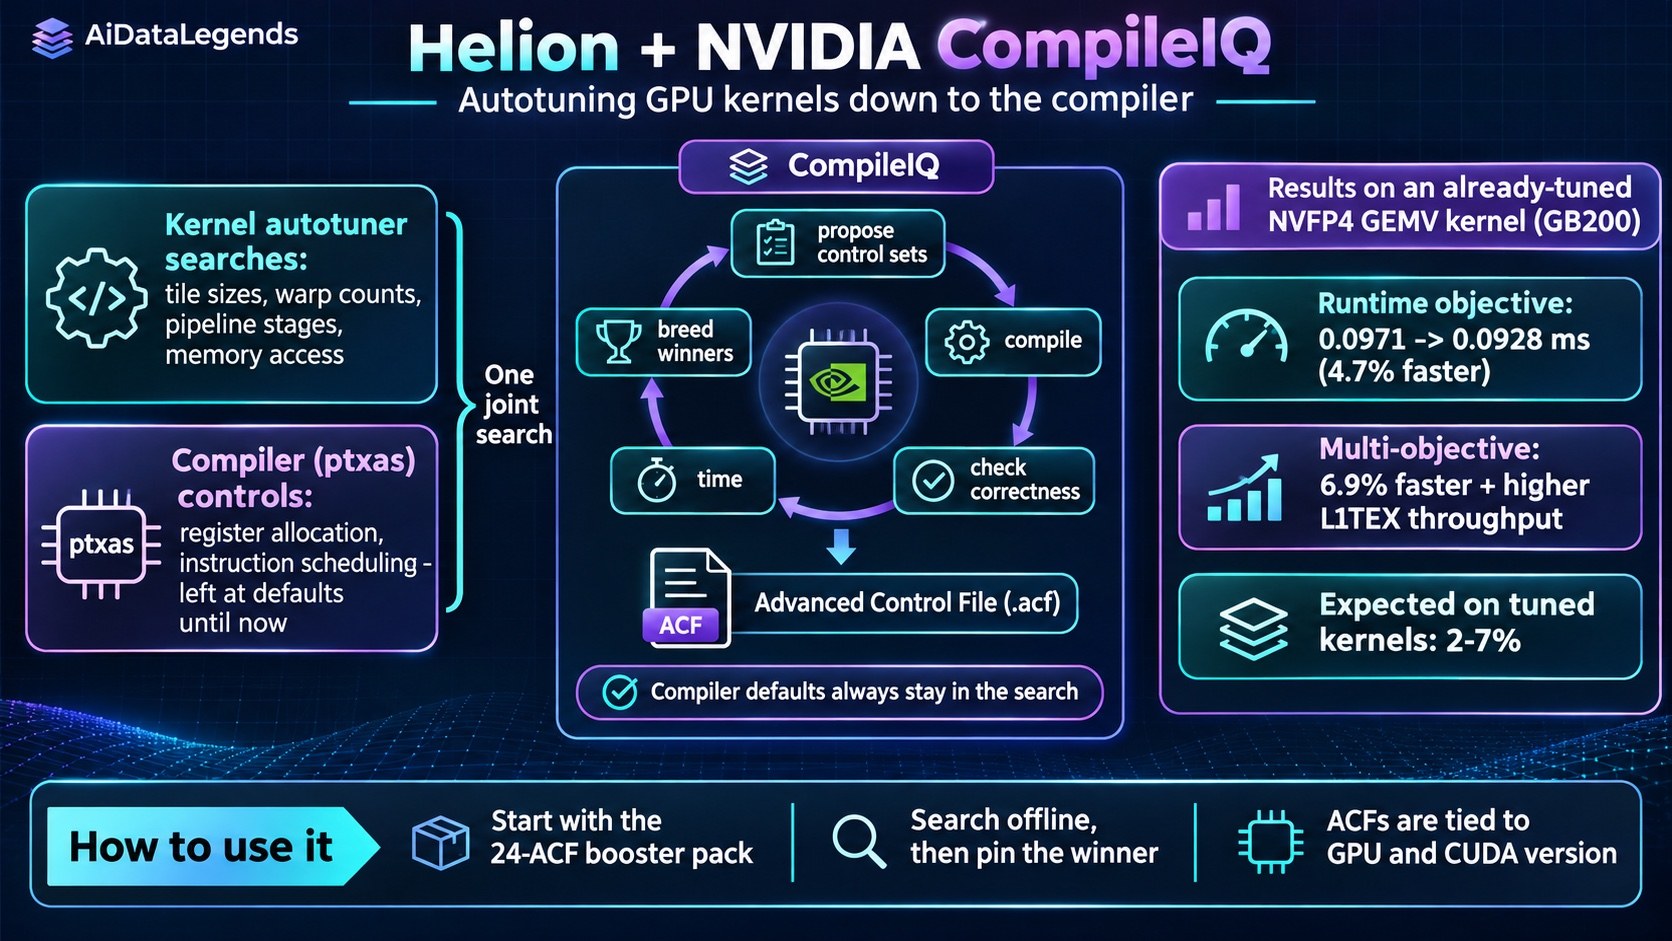
Kernel autotuners stop at tile sizes and warp counts. Helion can now search ptxas compiler controls in the same loop, using CompileIQ's Advanced Control Files, for 2 to 7% more speed on kernels already tuned.
Nov 19, 2026 · 4 min read
TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning
AI Engineering

TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning

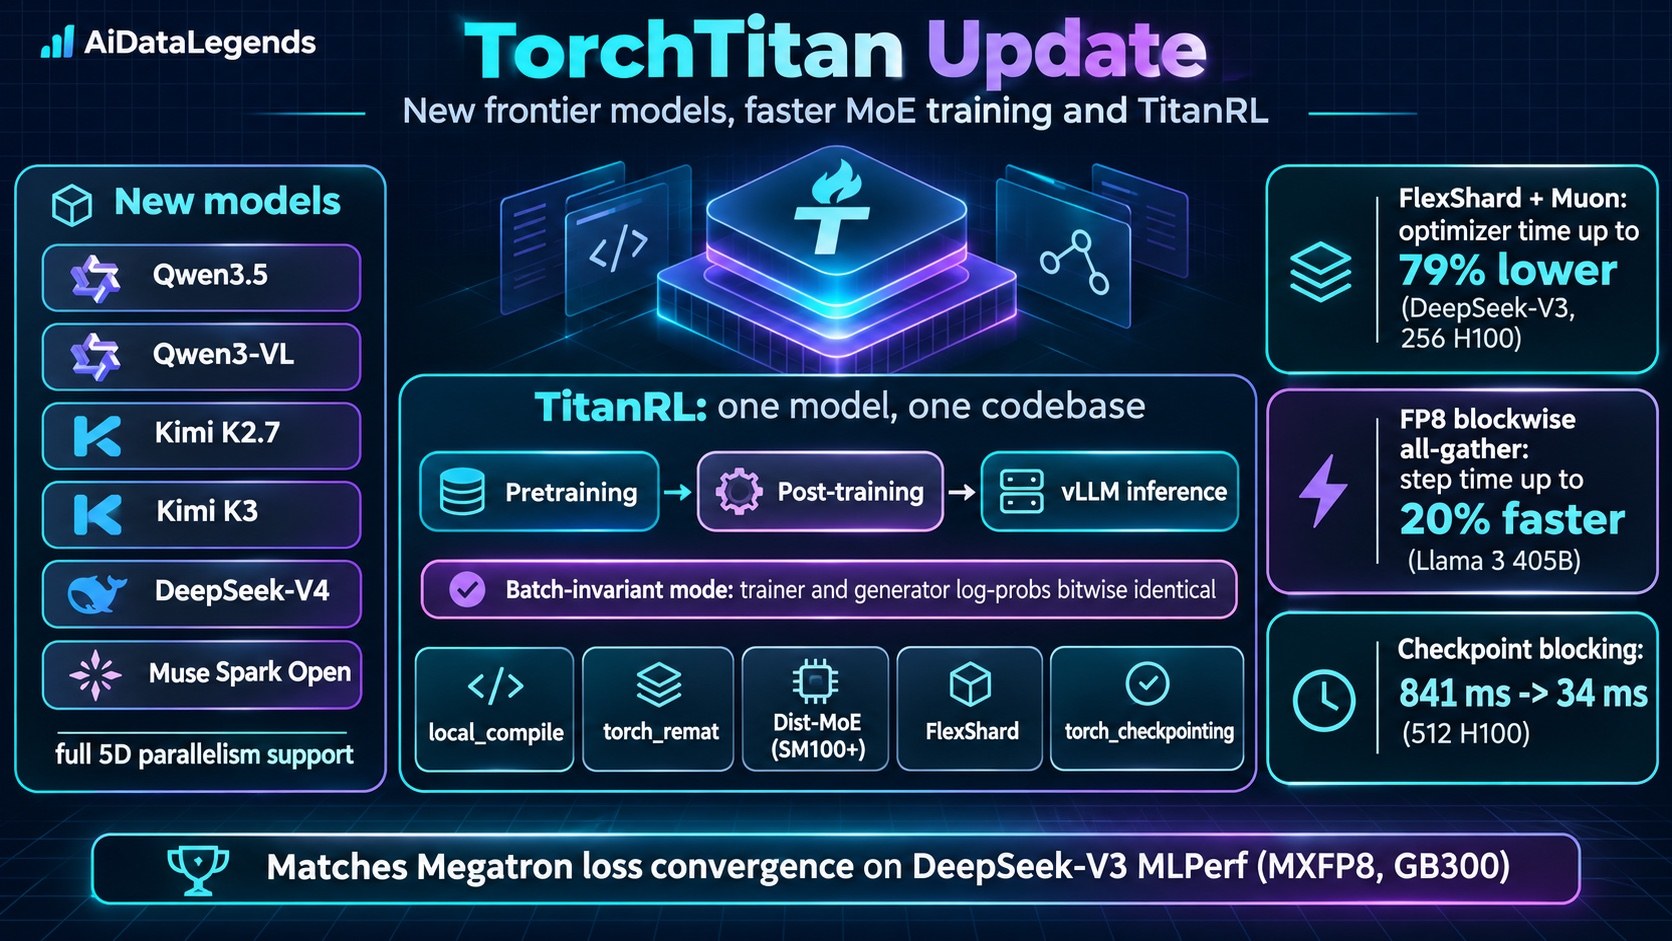
PyTorch's TorchTitan adds Qwen3.5, Kimi K3 and DeepSeek-V4, an RL stack whose trainer and generator can produce bitwise-identical log-probabilities, and FlexShard, which cut Muon optimizer time by up to 79%.

Nov 18, 2026 · 4 min read
Jev in SQL: Classify Text Columns in DuckDB and MotherDuck With Typed Answers
Data Engineering

Jev in SQL: Classify Text Columns in DuckDB and MotherDuck With Typed Answers

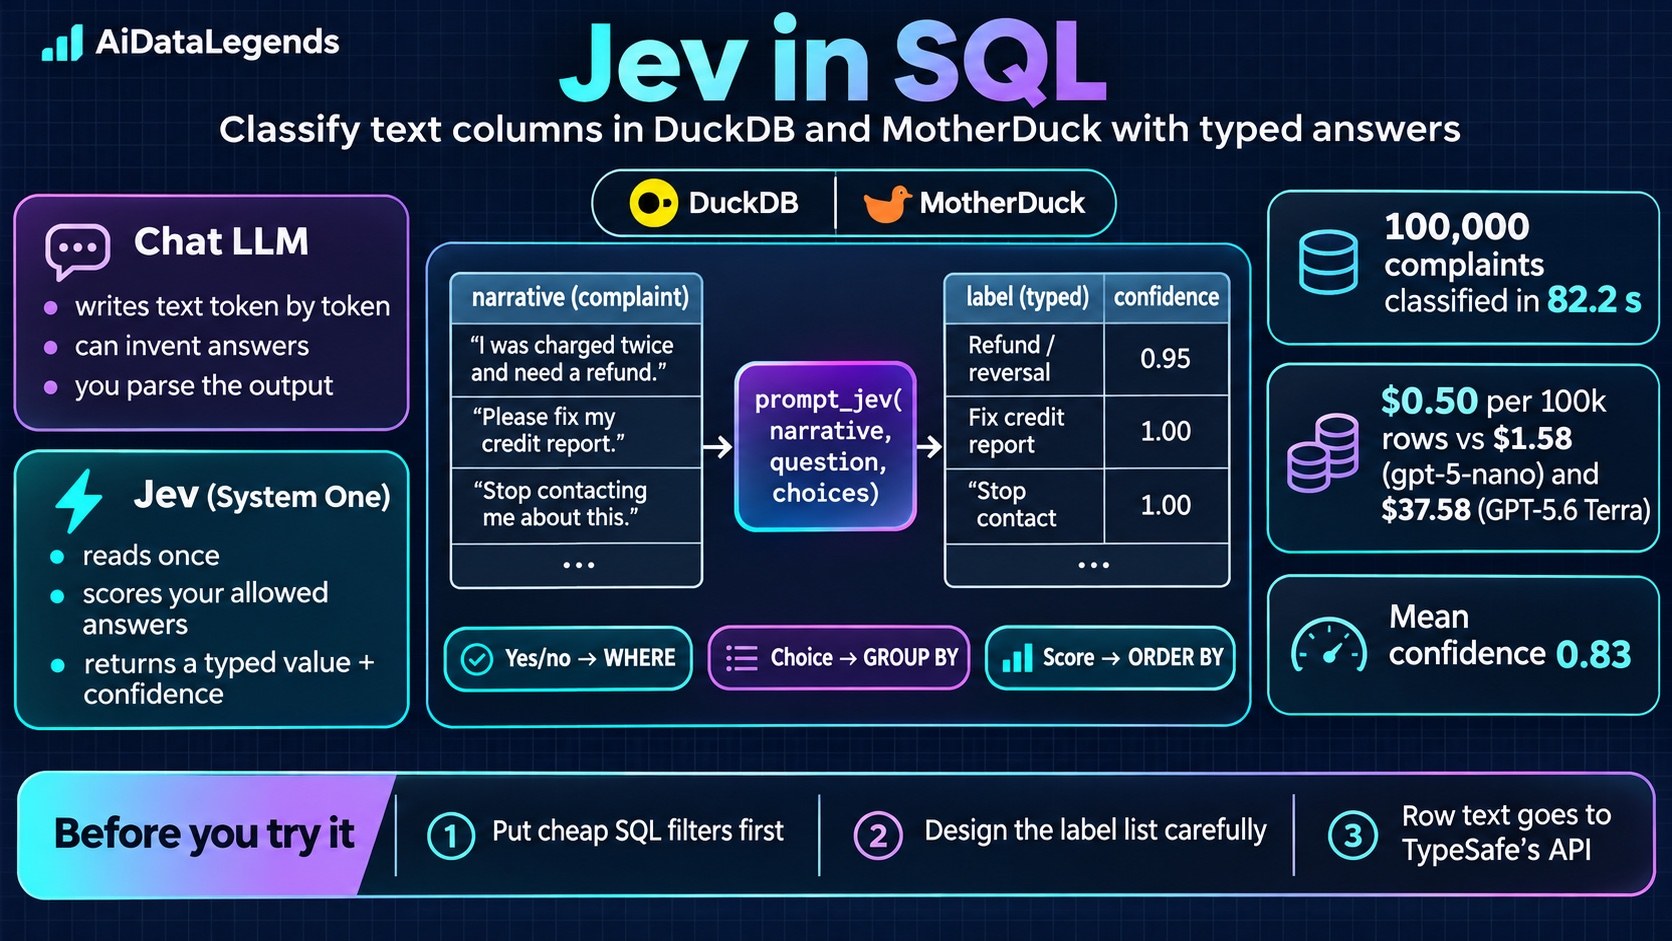
TypeSafe's Jev scores a fixed list of answers instead of writing text. MotherDuck classified 100,000 complaints in 82 seconds for $0.50, and DuckDB extensions turn plain-English conditions into WHERE clauses.

Nov 17, 2026 · 5 min read
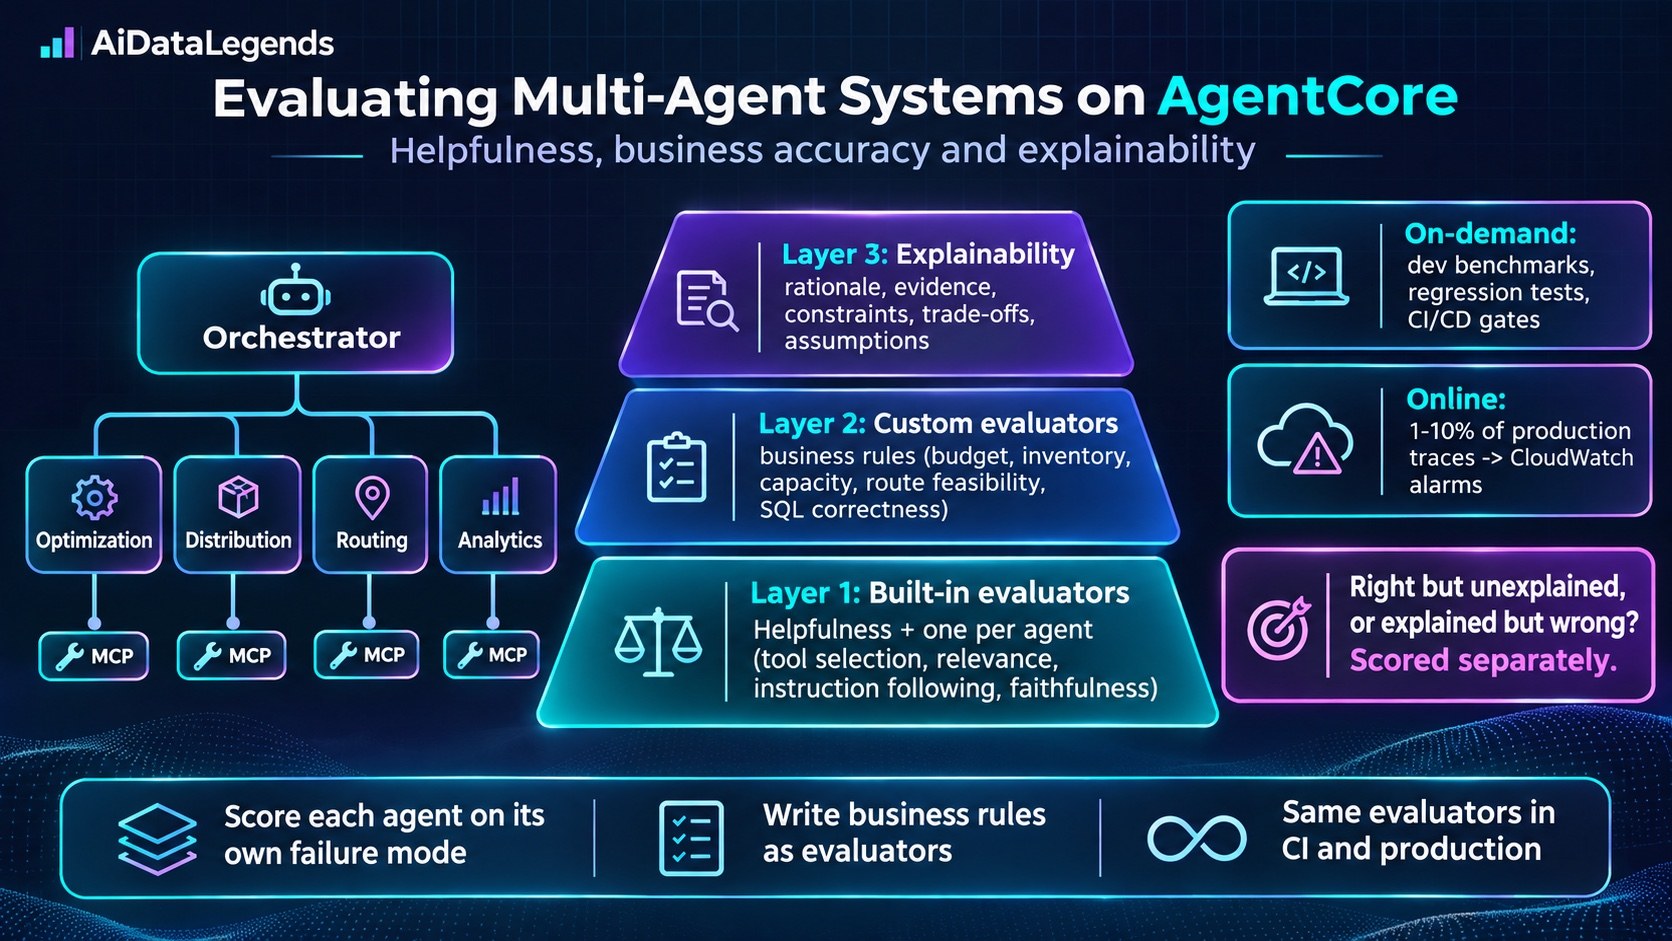
Evaluating Multi-Agent Systems With Amazon Bedrock AgentCore: Helpfulness, Business Accuracy and Explainability
AI Engineering

Evaluating Multi-Agent Systems With Amazon Bedrock AgentCore: Helpfulness, Business Accuracy and Explainability

AWS shows a three-layer way to test agents on AgentCore. Built-in evaluators set a baseline, custom evaluators check business rules, and separate explainability evaluators check whether agents can say why.

Nov 16, 2026 · 5 min read
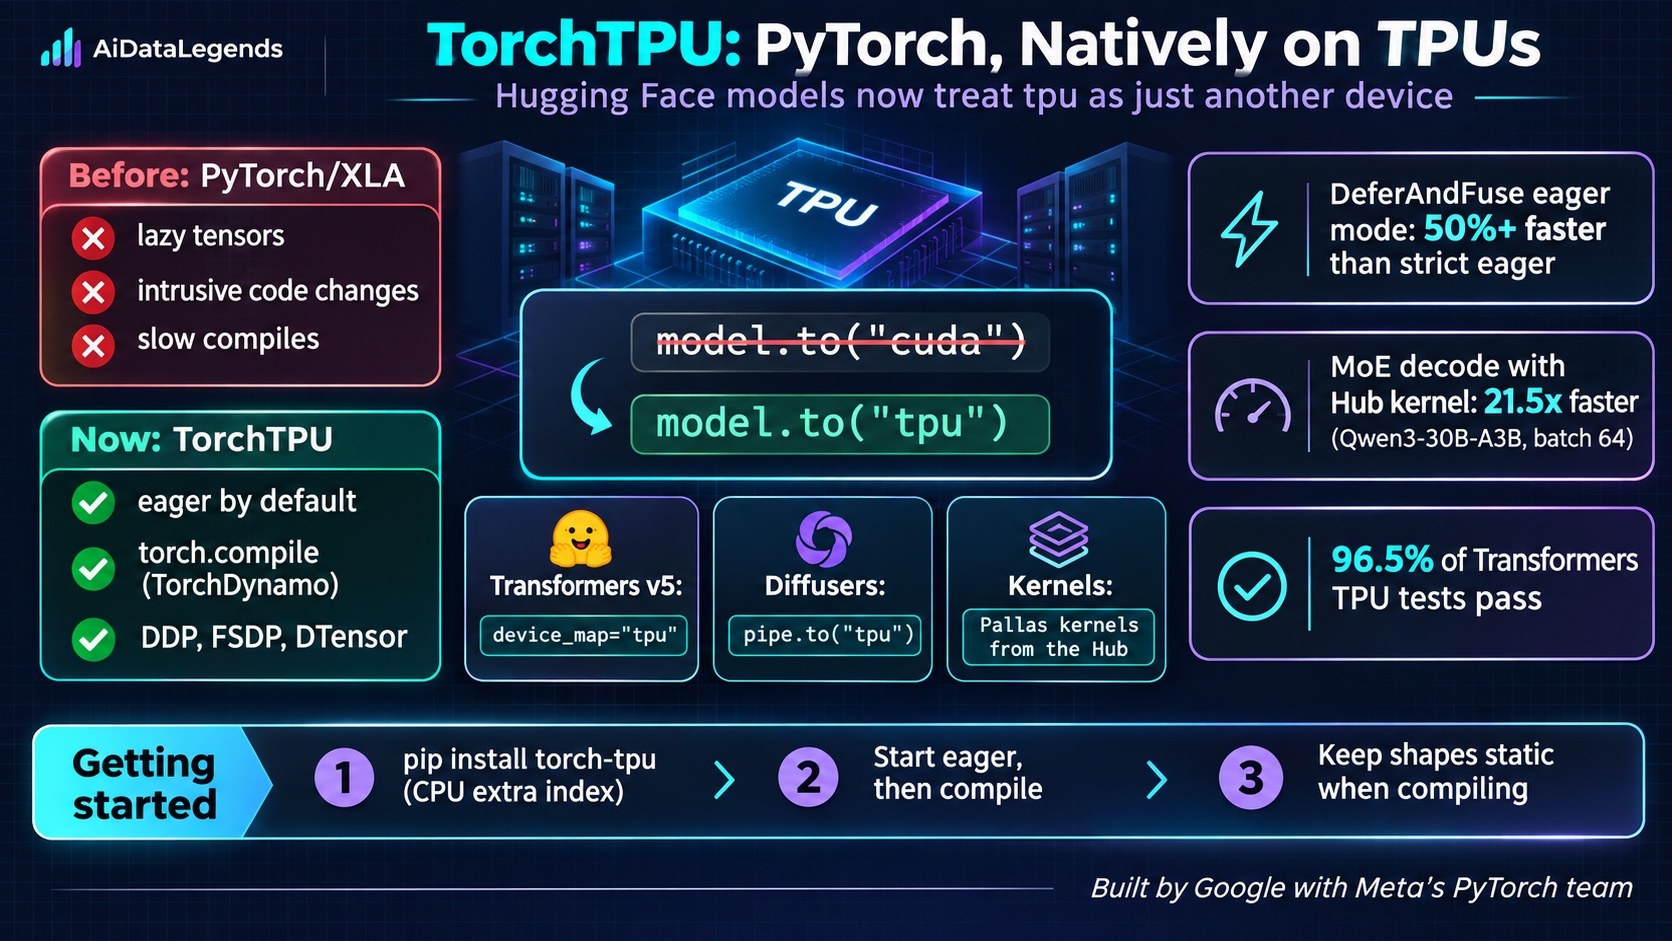
TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along
AI Engineering

TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along

Google and Meta built TorchTPU, a native PyTorch backend for TPUs with eager execution and torch.compile. Hugging Face Transformers, Diffusers and Kernels now treat "tpu" as just another device.

Nov 15, 2026 · 5 min read
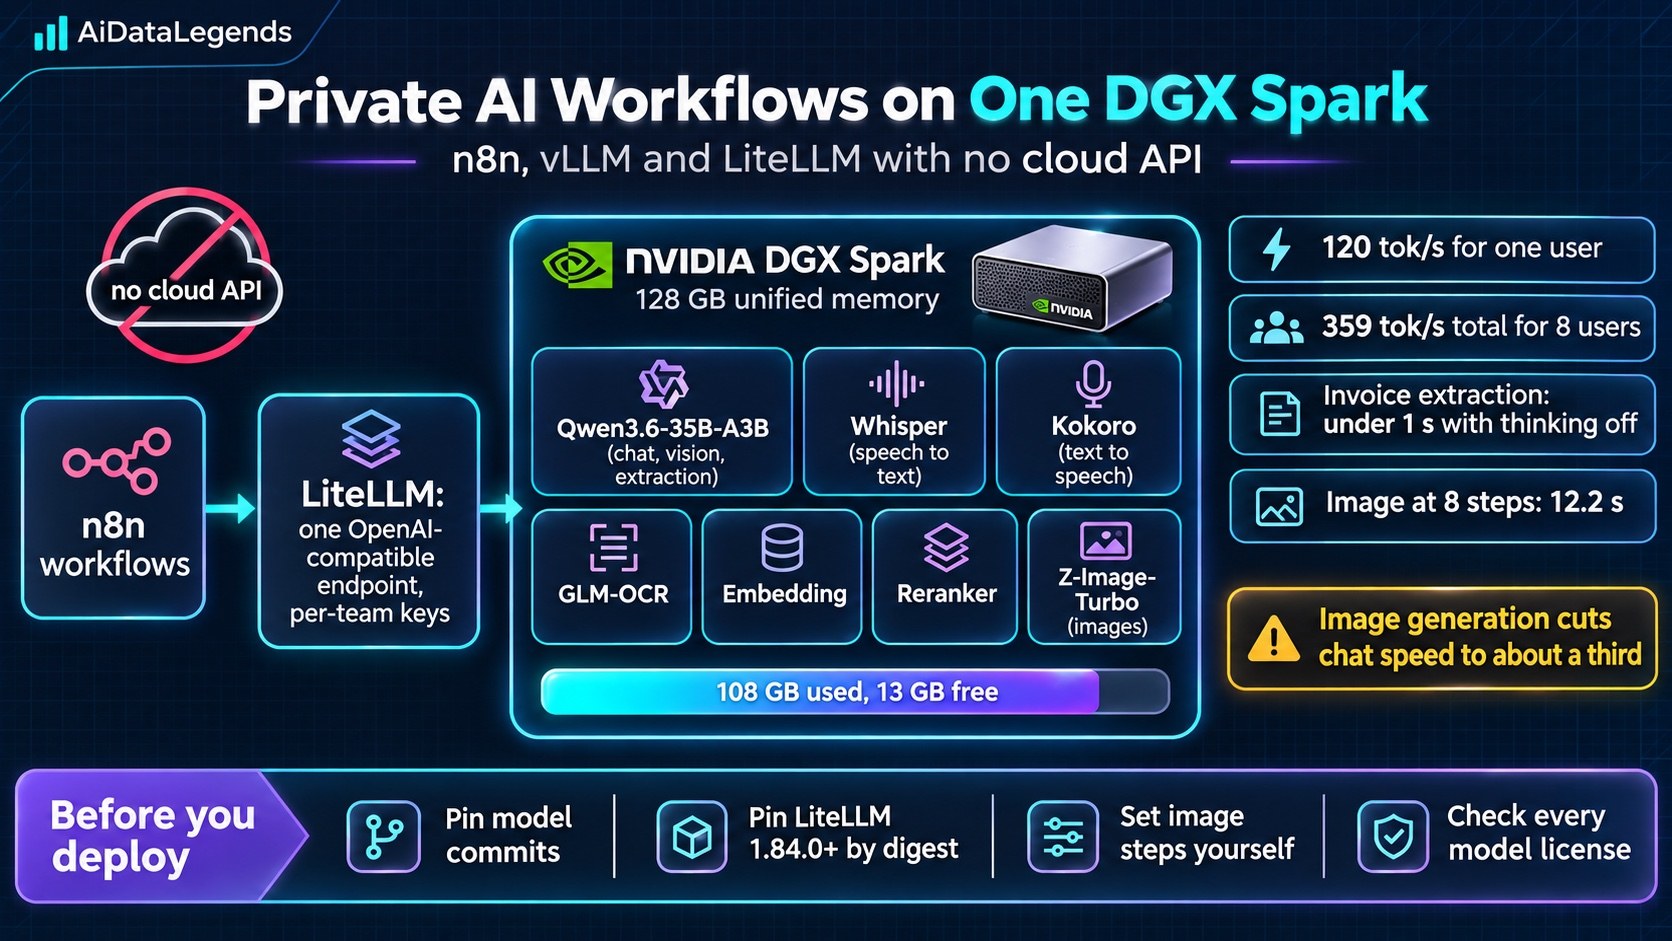
Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API
AI Engineering

Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API

n8n served seven models from one 128GB DGX Spark behind a single OpenAI-compatible endpoint. Qwen3.6-35B-A3B ran at 120 tokens per second for one user and 359 in total for eight, but image generation cut chat speed to a third.

Nov 14, 2026 · 5 min read
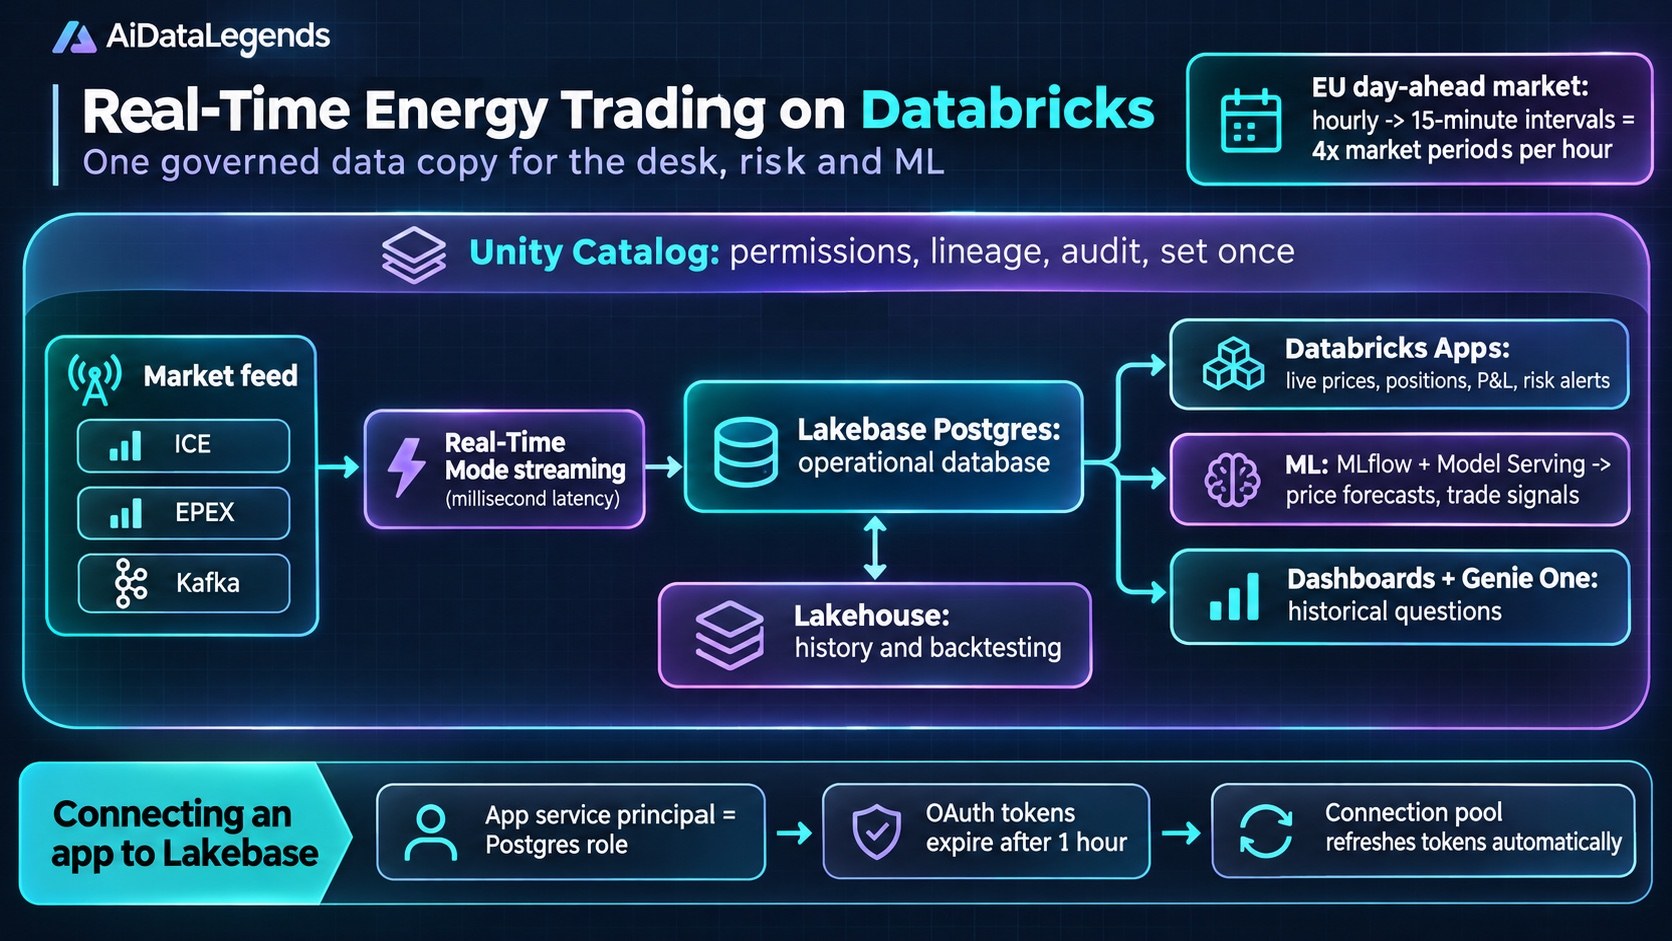
Real-Time Energy Trading on Databricks: One Governed Data Copy for the Desk, Risk and ML
Data Engineering

Real-Time Energy Trading on Databricks: One Governed Data Copy for the Desk, Risk and ML

Databricks streams market data with Real-Time Mode into Lakebase Postgres, serves the trading desk from it, and trains models and runs analytics on the same governed copy. Here is how the pieces fit, and how to wire an app to Lakebase.

Nov 13, 2026 · 5 min read
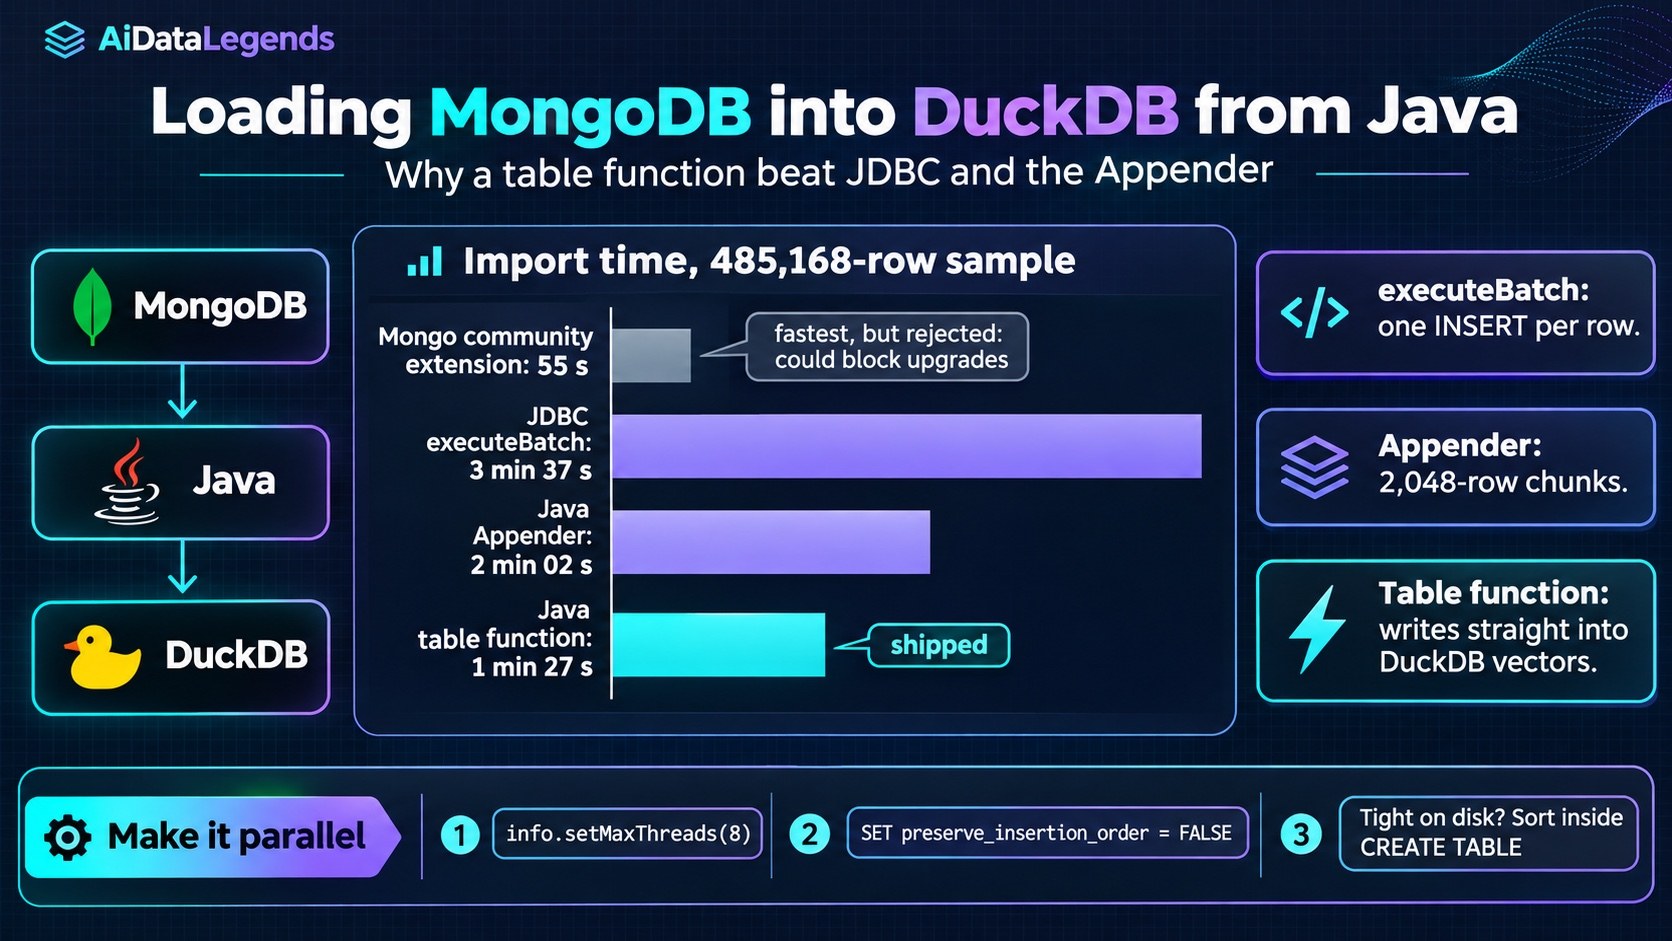
Loading MongoDB into DuckDB from Java: Why a Table Function Beat JDBC and the Appender
Data Engineering

Loading MongoDB into DuckDB from Java: Why a Table Function Beat JDBC and the Appender

On a 485,168-record sample, a pure-Java table function loaded data in 1m 27s, against 2m 02s for the Appender and 3m 37s for JDBC batches. On production data it matched the Mongo community extension.

Nov 12, 2026 · 5 min read
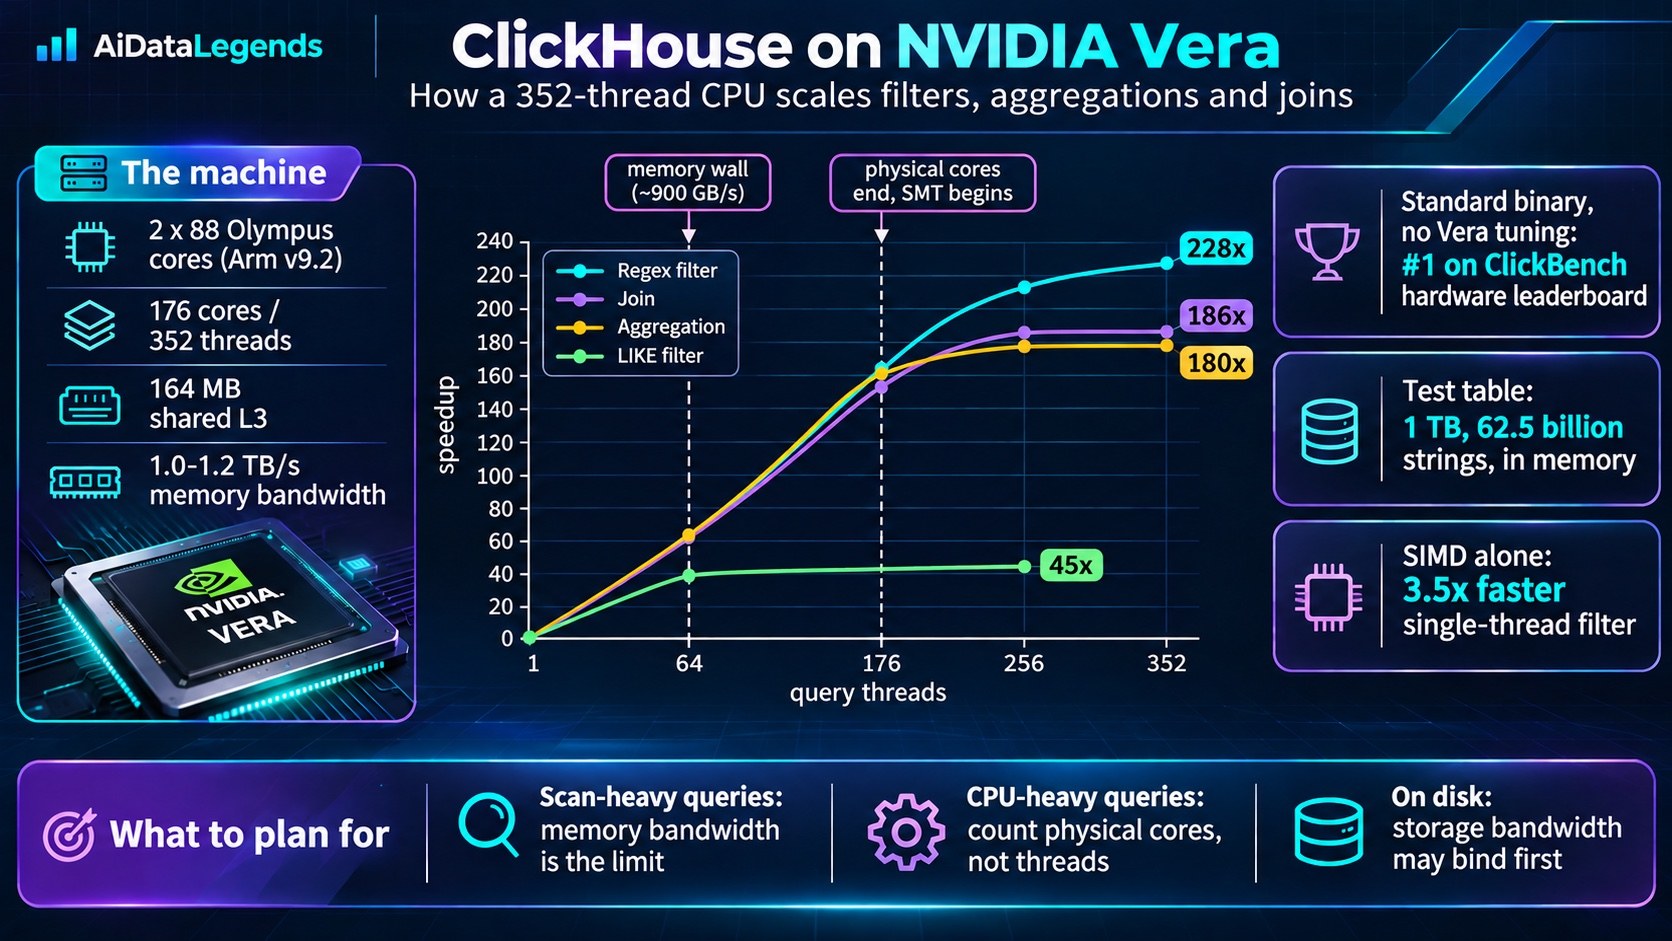
ClickHouse on NVIDIA Vera: How a 352-Thread CPU Scales Filters, Aggregations and Joins
Data Engineering

ClickHouse on NVIDIA Vera: How a 352-Thread CPU Scales Filters, Aggregations and Joins

An unmodified ClickHouse binary scales almost linearly to Vera's 176 physical cores on CPU-heavy queries. Past that, SMT adds little, and a simple LIKE filter runs out of memory bandwidth at 64 threads.

Nov 11, 2026 · 5 min read
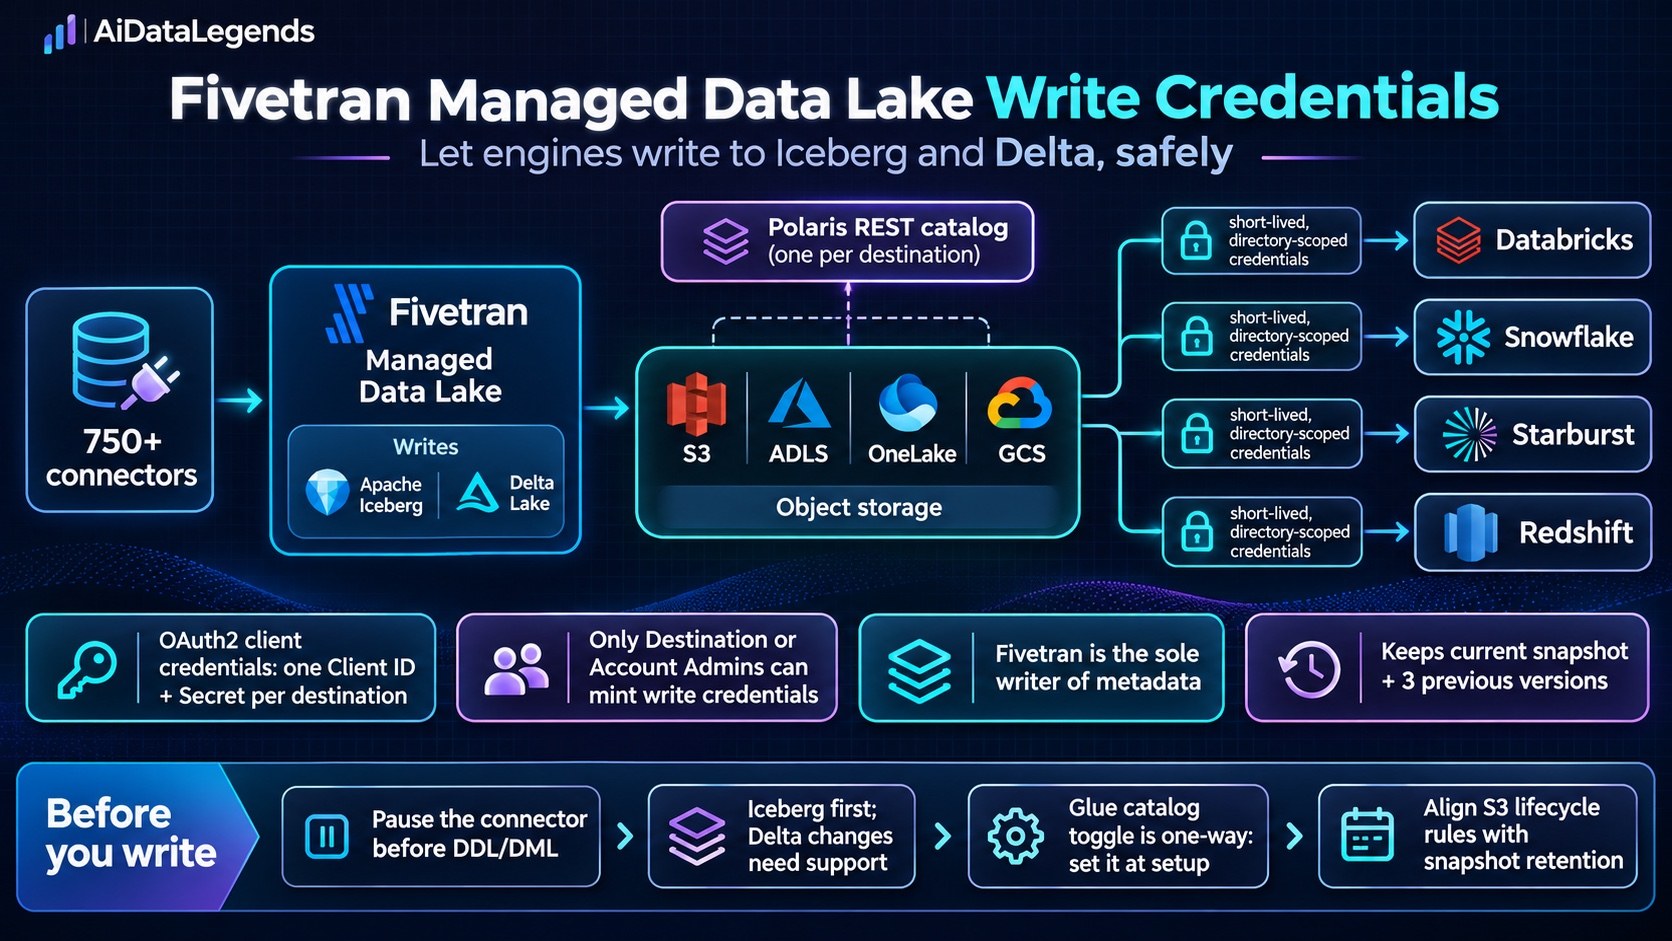
Fivetran Managed Data Lake Write Credentials: Letting Engines Write to Iceberg and Delta Safely
Data Engineering

Fivetran Managed Data Lake Write Credentials: Letting Engines Write to Iceberg and Delta Safely

By issuing short-lived, directory-scoped credentials against a Polaris-backed REST catalog, MDLS lets engines alter Iceberg and Delta tables without sharing Fivetran's long-lived keys or breaking the write-once metadata model.

Nov 10, 2026 · 6 min read
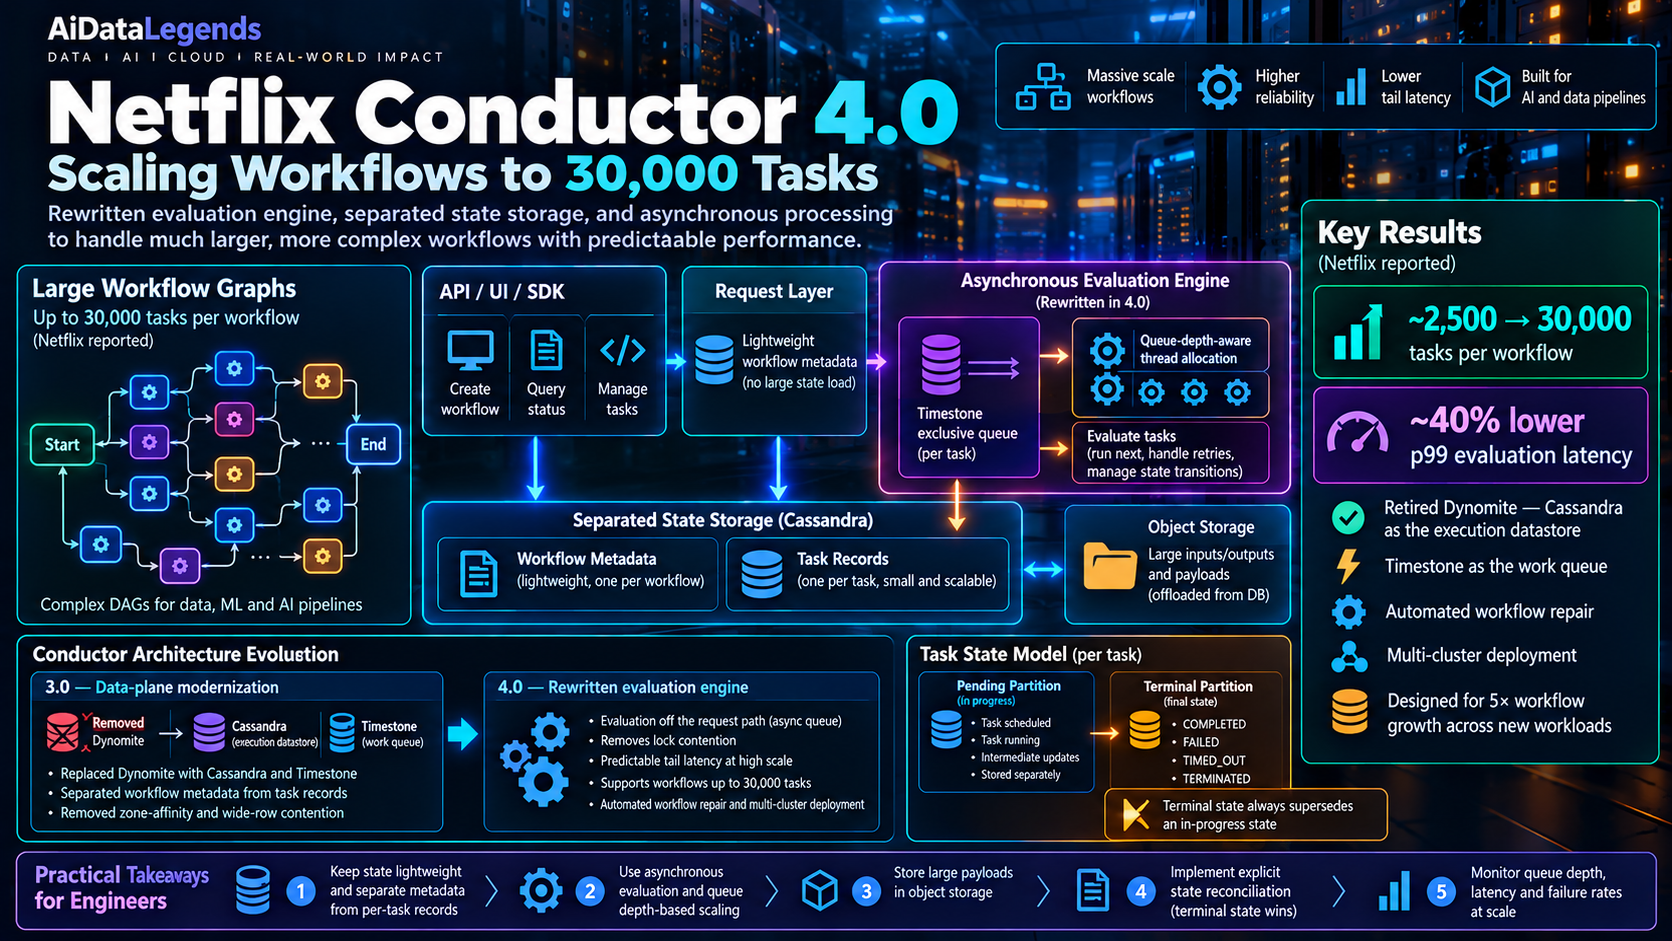
Netflix Conductor 4.0: Scaling Workflows to 30,000 Tasks with Asynchronous Evaluation
Data Engineering

Netflix Conductor 4.0: Scaling Workflows to 30,000 Tasks with Asynchronous Evaluation

Netflix redesigned Conductor’s workflow engine by separating task records from workflow metadata, moving evaluation off the request path, and using Timestone for ordered asynchronous processing. The company reports support for workflows of up to 30,000 tasks and roughly 40% lower p99 evaluation latency.

Oct 28, 2026 · 16 min read
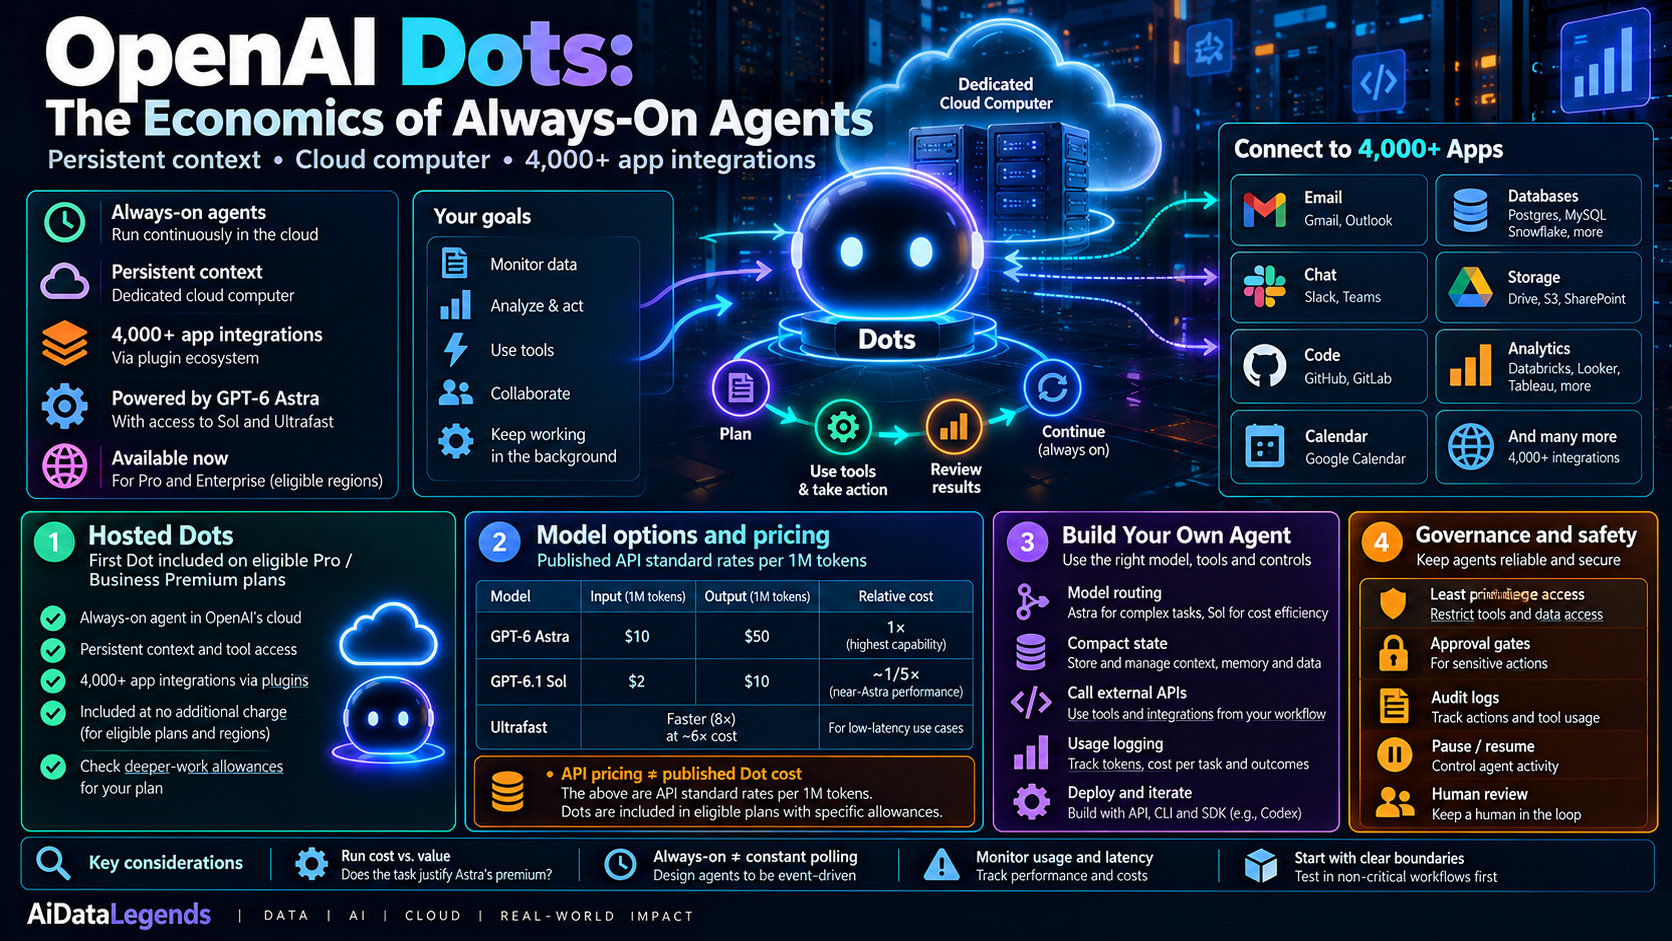
OpenAI Dots: A Persistent Cloud Agent for 4,000+ Apps
AI Engineering

OpenAI Dots: A Persistent Cloud Agent for 4,000+ Apps

Dots gives Pro and Business Premium users a dedicated cloud computer powered by GPT-6 Astra, but its high default cost makes the cheaper GPT-6.1 Sol a critical consideration for engineers.

Oct 26, 2026 · 4 min read
How IFCO Cut a 7-Hour dbt Job to 2 Hours 20 Minutes on Databricks
Data Engineering

How IFCO Cut a 7-Hour dbt Job to 2 Hours 20 Minutes on Databricks

IFCO reduced its core dbt job runtime by about 66% and daily compute costs by 58% by fixing incremental-write behaviour, inspecting actual execution plans, and splitting a large dbt graph into individual Databricks tasks—with model-level diagnostics and targeted recovery.

Oct 16, 2026 · 14 min read
ClickHouse Cloud Executable UDFs GA: Native Code, Network Access, and Query-Level Metrics
Data Engineering

ClickHouse Cloud Executable UDFs GA: Native Code, Network Access, and Query-Level Metrics

ClickHouse Cloud now supports compiled-language UDFs, outbound network access for eligible UDF runtimes, and per-query execution metrics. For LLM observability, that means token accounting and sampled quality evaluation can live closer to the data—with important resource, security, and runtime trade-offs.

Oct 14, 2026 · 14 min read
Meta Open-Sources Stateless NTS: Authenticated Time Without Server-Side Cookie State
Data Engineering

Meta Open-Sources Stateless NTS: Authenticated Time Without Server-Side Cookie State

Meta has open-sourced its Network Time Security implementation and launched nts.meta.com. Here is how its stateless cookie design derives sealing keys from a master secret and the epoch day, how to try it with chrony, and what NTS still cannot fix.

Oct 12, 2026 · 12 min read
n8n Bridges Workflow Automation and API Management, With Important Trade-offs
Data Engineering

n8n Bridges Workflow Automation and API Management, With Important Trade-offs

n8n combines self-hosted workflow orchestration, webhook-driven endpoints, custom code and AI integrations. It can reduce the need for separate integration infrastructure, but API security, traffic governance and production reliability still require deliberate design.

Oct 11, 2026 · 12 min read
Databricks SQL Serverless Cost Governance: Budgets, Alerts, and Query-Level Attribution
Data Engineering

Databricks SQL Serverless Cost Governance: Budgets, Alerts, and Query-Level Attribution

Databricks adds budgets, billing system tables and usage dashboards to make SQL Serverless spend easier to explain. But budgets are not spending caps, estimates are not invoices, and useful attribution depends on consistent tagging and operational controls.

Oct 10, 2026 · 13 min read
Databricks Runtime Introduces NEAREST BY: Native SQL Vector Search at Scale
Data Engineering

Databricks Runtime Introduces NEAREST BY: Native SQL Vector Search at Scale

Databricks brings batch vector search into SQL with NEAREST BY, a fused Photon GEMM operator and IVF indexes stored in liquid-clustered Delta tables, reducing the need for separate vector-serving infrastructure in large-scale analytical workloads.

Oct 09, 2026 · 12 min read
Google Research Proposes Contextual Integrity Policy Engines and Multi-Agent Benchmarks for Agentic Privacy
AI Engineering

Google Research Proposes Contextual Integrity Policy Engines and Multi-Agent Benchmarks for Agentic Privacy

A Google Research workshop report proposes LLM-driven policy engines based on contextual integrity, plus standardized multi-agent benchmarks, to make AI agents more privacy-aware, auditable and safer to deploy. What it means for data and AI engineers.

Oct 08, 2026 · 13 min read
Databricks Lakehouse Platform for Real-Time, Agentic Data and AI Workloads
Data Engineering

Databricks Lakehouse Platform for Real-Time, Agentic Data and AI Workloads

Databricks is pushing the lakehouse beyond analytics: federated and streaming data, transactional serving, AI Search and agents can share one governed data foundation. What that changes for data and AI engineers, and where the limits are.

Oct 07, 2026 · 13 min read
GPT-6.1 Sol on Amazon Bedrock: Near-Astra performance at a fraction of the cost
AI Engineering

GPT-6.1 Sol on Amazon Bedrock: Near-Astra performance at a fraction of the cost

OpenAI's GPT-6.1 Sol brings near-Astra performance to coding, computer use and professional work at one-fifth of Astra's standard token prices. Here's what Amazon Bedrock adds, from pricing and a 1M-token context to endpoints and code.

Oct 06, 2026 · 13 min read
Grok 4.7 on Amazon Bedrock: Routing, reasoning effort, and cost with OpenAI-compatible APIs
AI Engineering

Grok 4.7 on Amazon Bedrock: Routing, reasoning effort, and cost with OpenAI-compatible APIs

xAI's Grok 4.7 is now on Amazon Bedrock with a 500K-token context window. Here's how reasoning effort, Geo vs Global routing and service tiers change cost and latency, with OpenAI-compatible code you can reuse.

Oct 05, 2026 · 9 min read