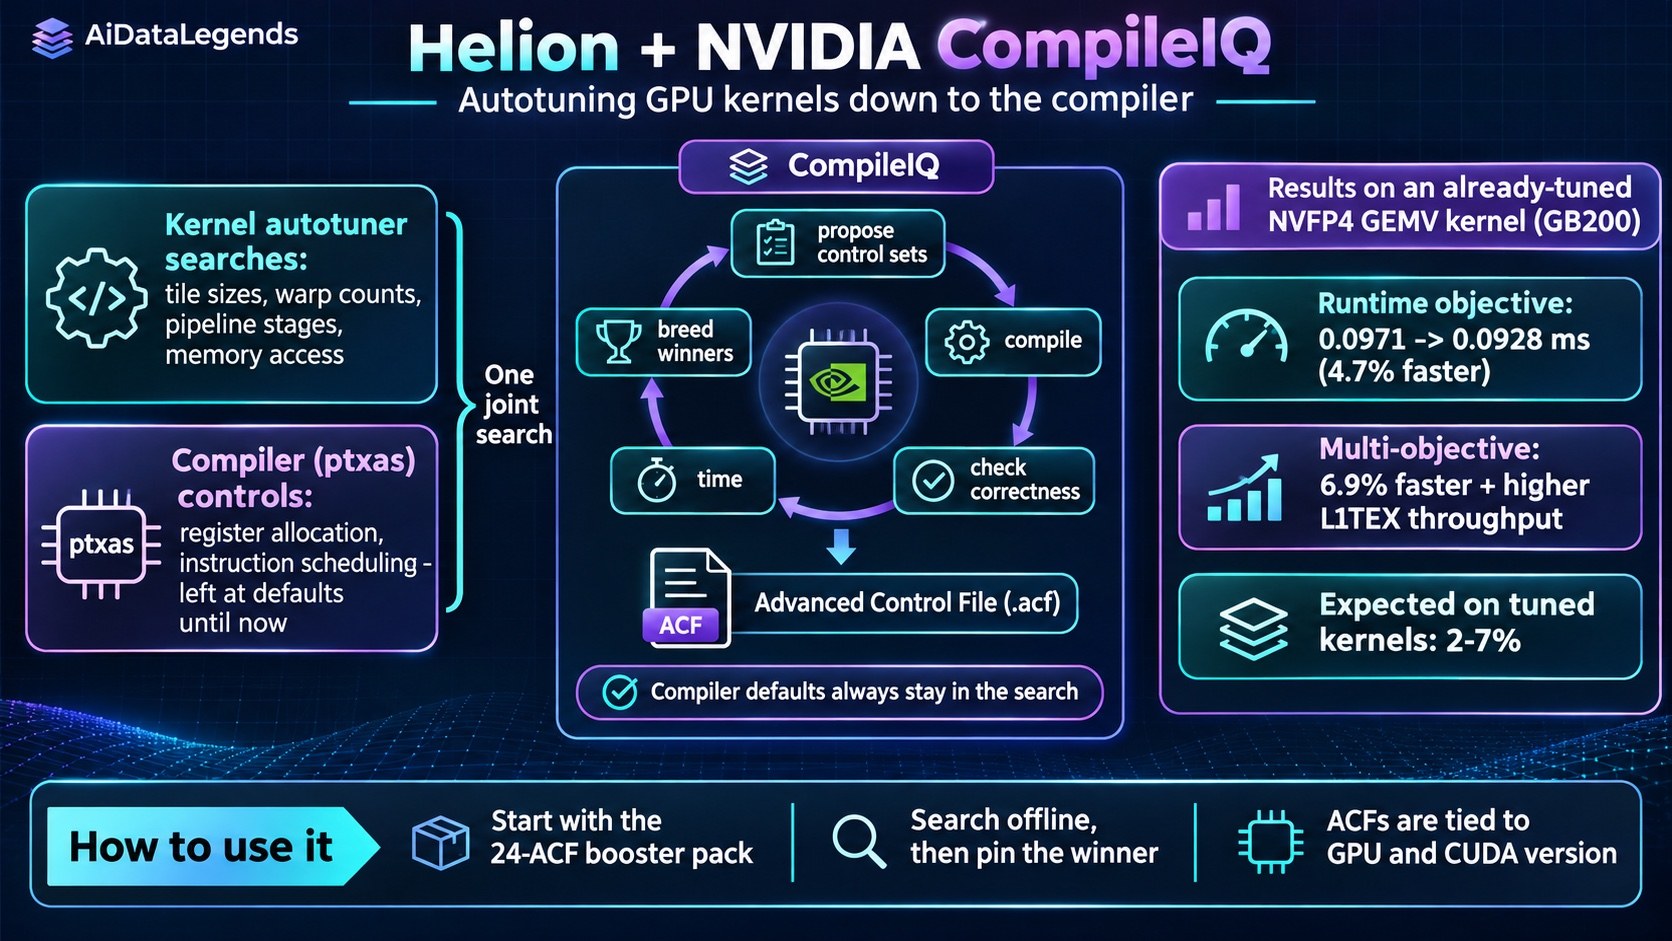
Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler
AI Engineering

Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler

Kernel autotuners stop at tile sizes and warp counts. Helion can now search ptxas compiler controls in the same loop, using CompileIQ's Advanced Control Files, for 2 to 7% more speed on kernels already tuned.
Nov 19, 2026 · 4 min read
TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning
AI Engineering

TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning

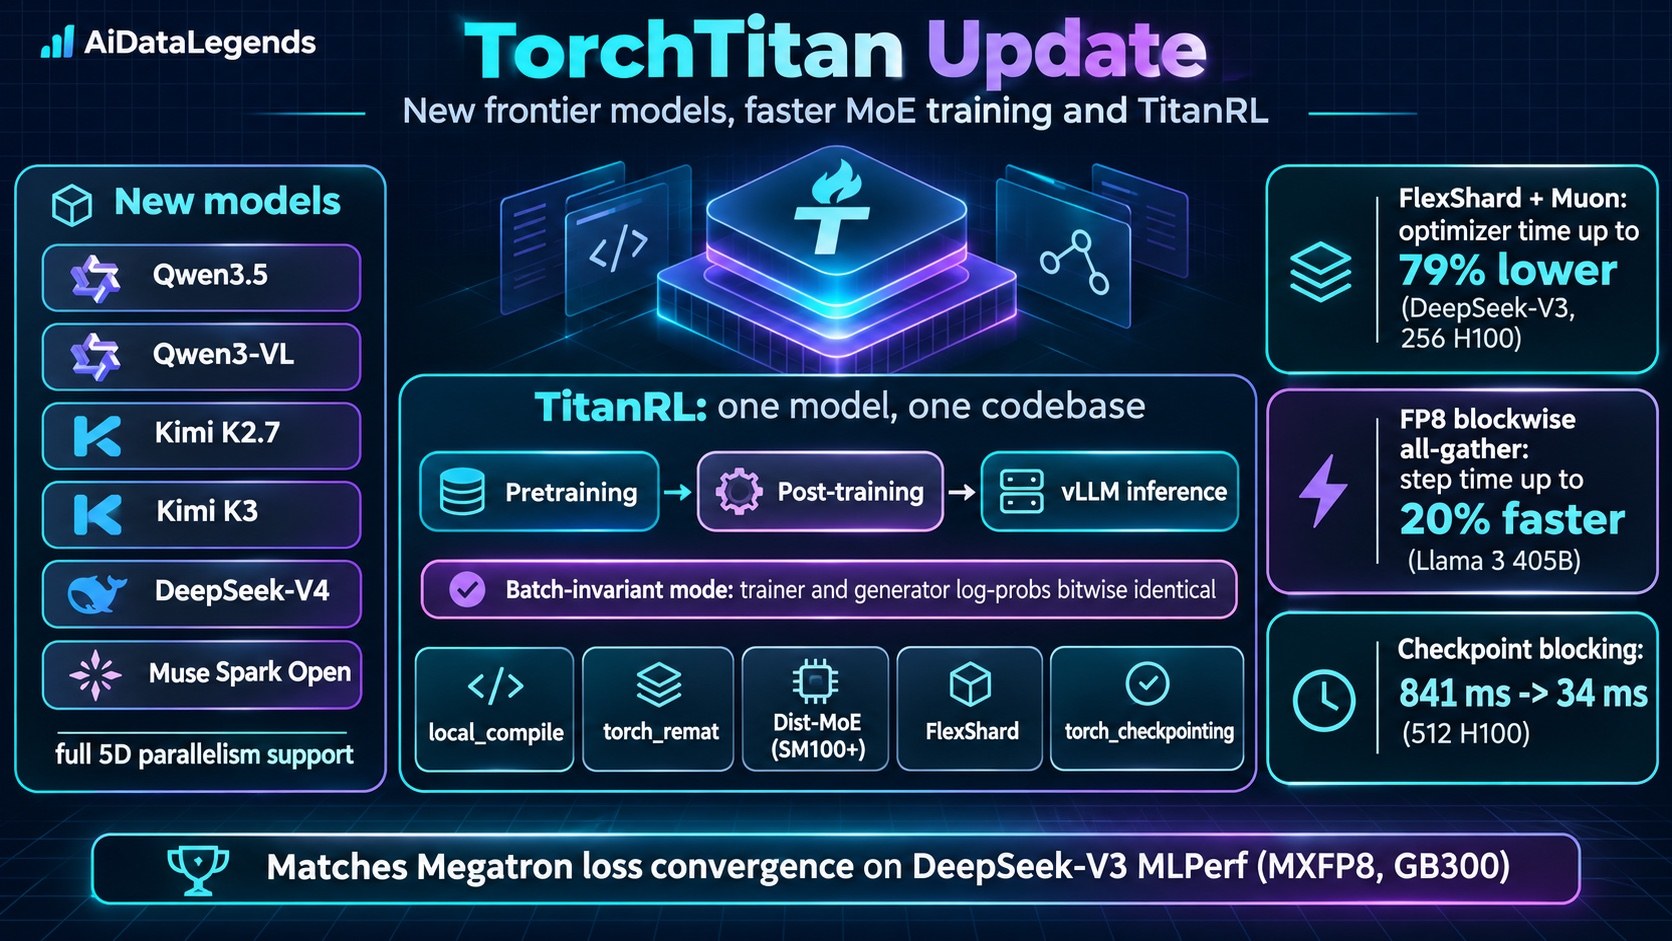
PyTorch's TorchTitan adds Qwen3.5, Kimi K3 and DeepSeek-V4, an RL stack whose trainer and generator can produce bitwise-identical log-probabilities, and FlexShard, which cut Muon optimizer time by up to 79%.

Nov 18, 2026 · 4 min read
Jev in SQL: Classify Text Columns in DuckDB and MotherDuck With Typed Answers
Data Engineering

Jev in SQL: Classify Text Columns in DuckDB and MotherDuck With Typed Answers

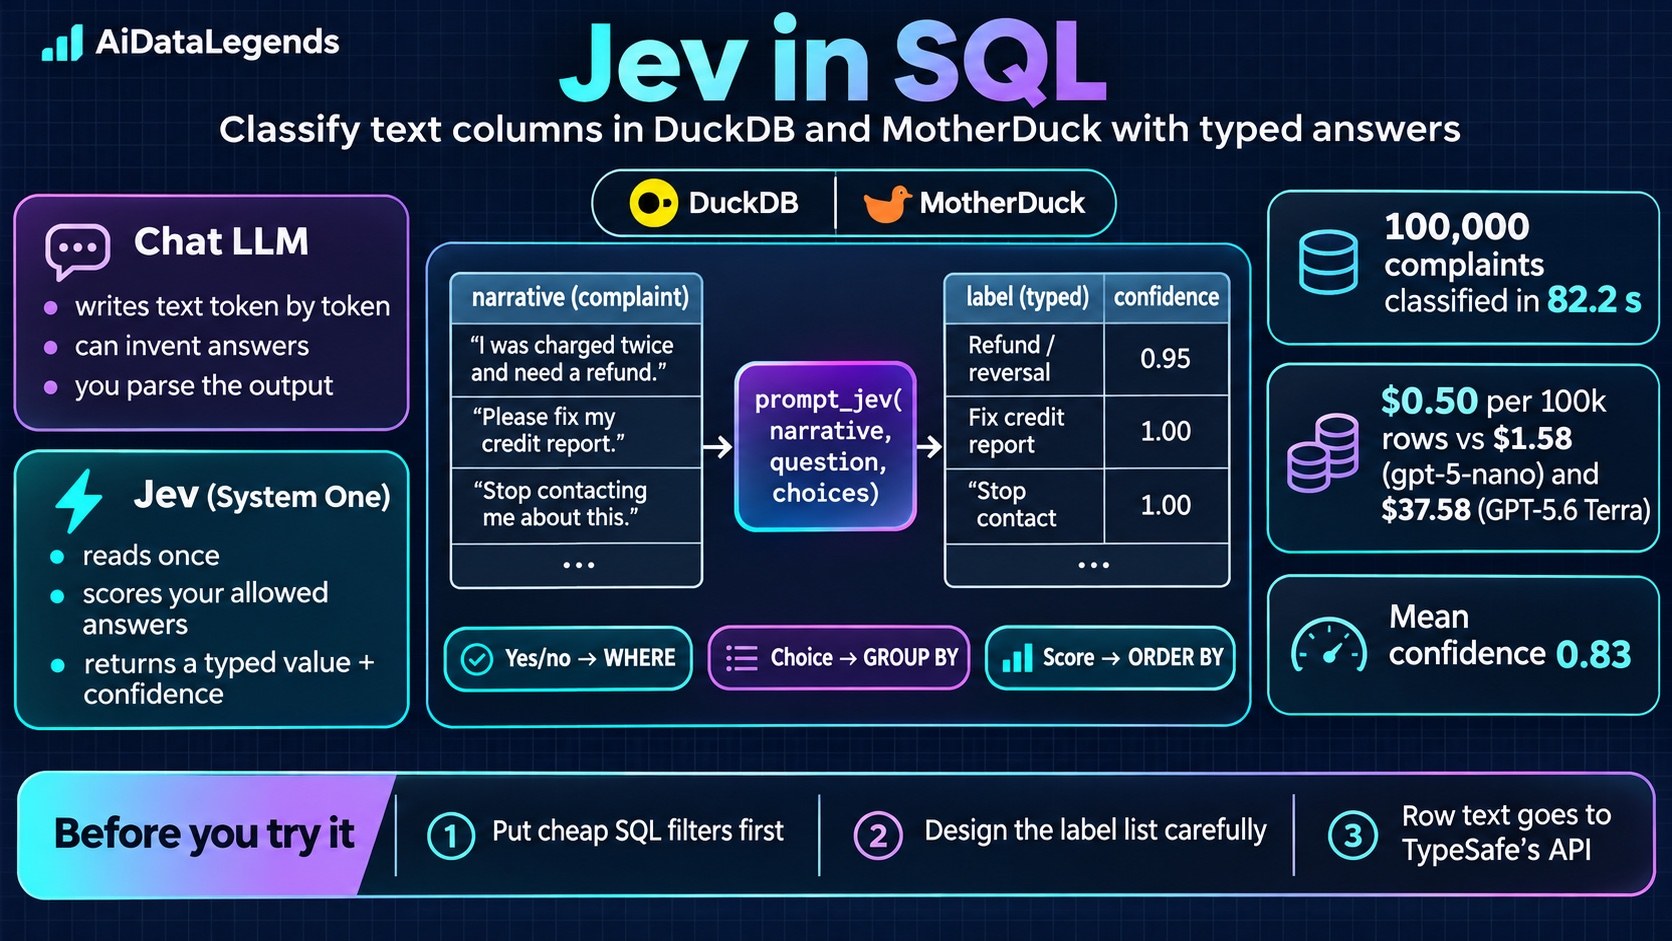
TypeSafe's Jev scores a fixed list of answers instead of writing text. MotherDuck classified 100,000 complaints in 82 seconds for $0.50, and DuckDB extensions turn plain-English conditions into WHERE clauses.

Nov 17, 2026 · 5 min read
Evaluating Multi-Agent Systems With Amazon Bedrock AgentCore: Helpfulness, Business Accuracy and Explainability
AI Engineering

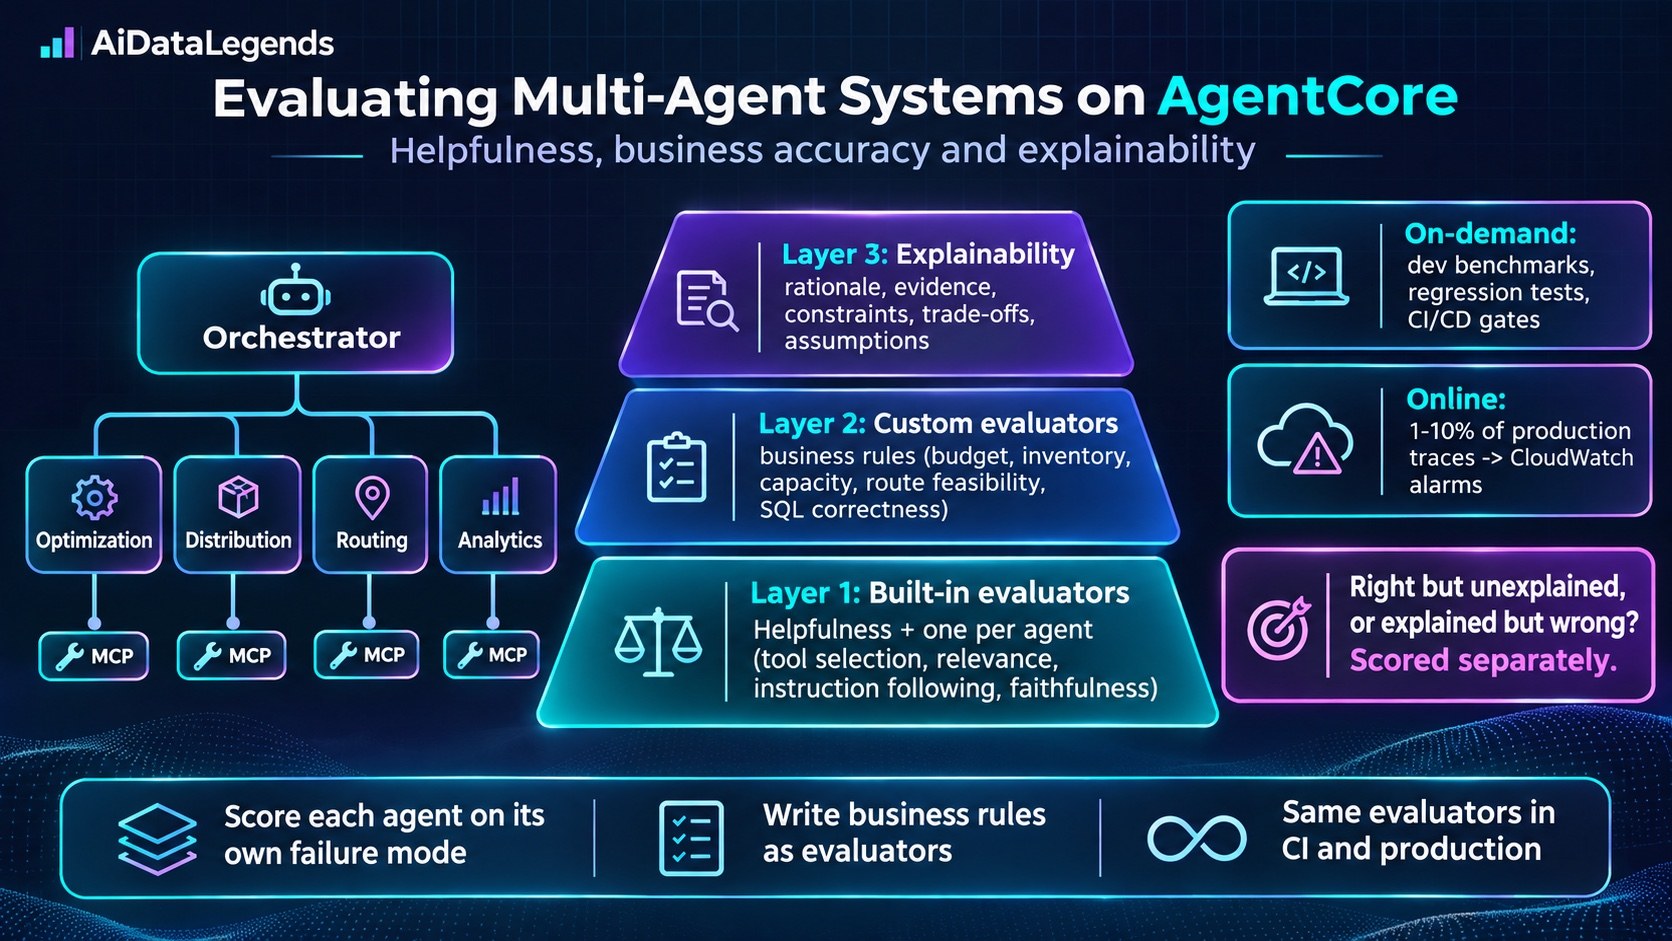
Evaluating Multi-Agent Systems With Amazon Bedrock AgentCore: Helpfulness, Business Accuracy and Explainability

AWS shows a three-layer way to test agents on AgentCore. Built-in evaluators set a baseline, custom evaluators check business rules, and separate explainability evaluators check whether agents can say why.

Nov 16, 2026 · 5 min read
TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along
AI Engineering

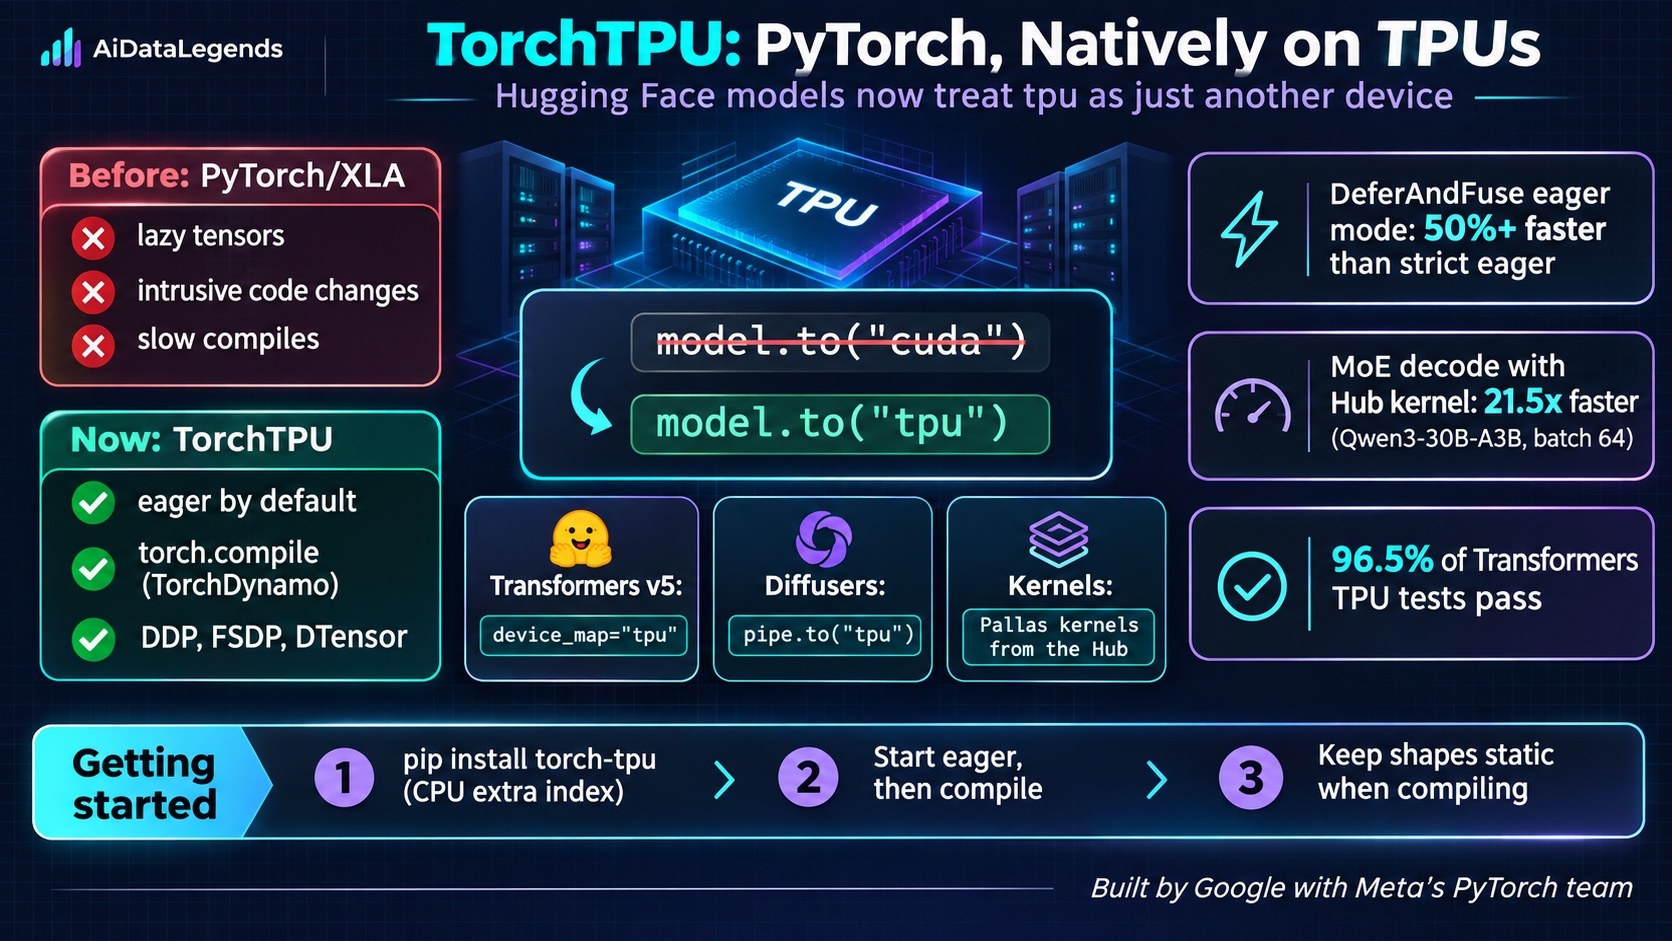
TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along

Google and Meta built TorchTPU, a native PyTorch backend for TPUs with eager execution and torch.compile. Hugging Face Transformers, Diffusers and Kernels now treat "tpu" as just another device.

Nov 15, 2026 · 5 min read
Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API
AI Engineering

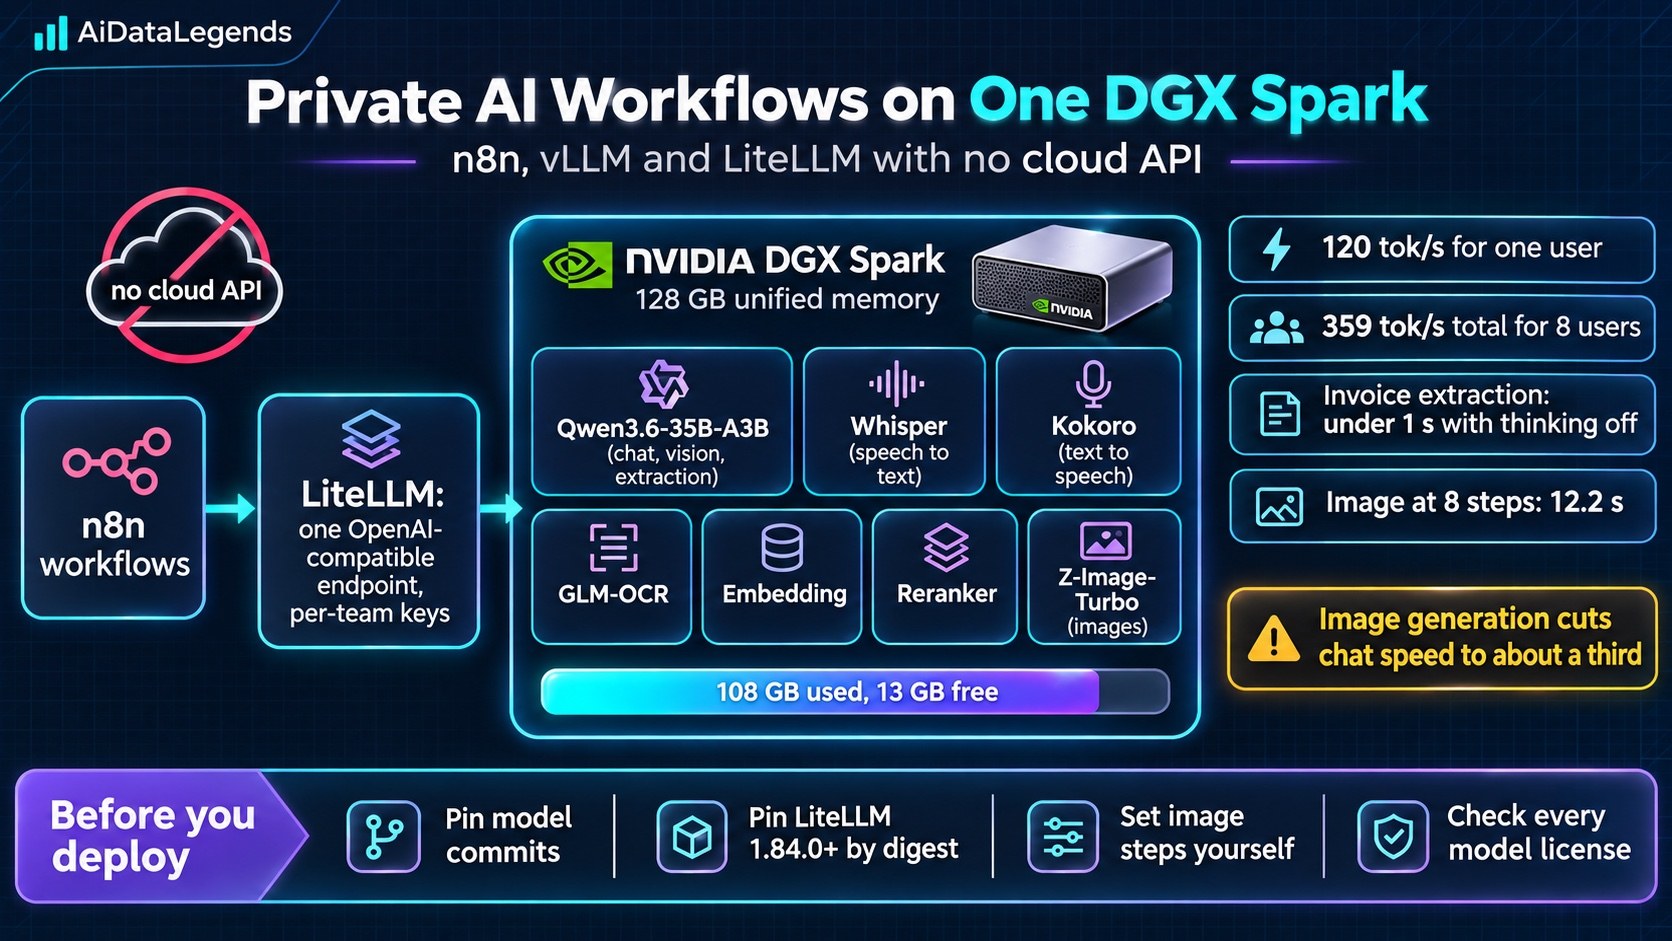
Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API

n8n served seven models from one 128GB DGX Spark behind a single OpenAI-compatible endpoint. Qwen3.6-35B-A3B ran at 120 tokens per second for one user and 359 in total for eight, but image generation cut chat speed to a third.

Nov 14, 2026 · 5 min read
Real-Time Energy Trading on Databricks: One Governed Data Copy for the Desk, Risk and ML
Data Engineering

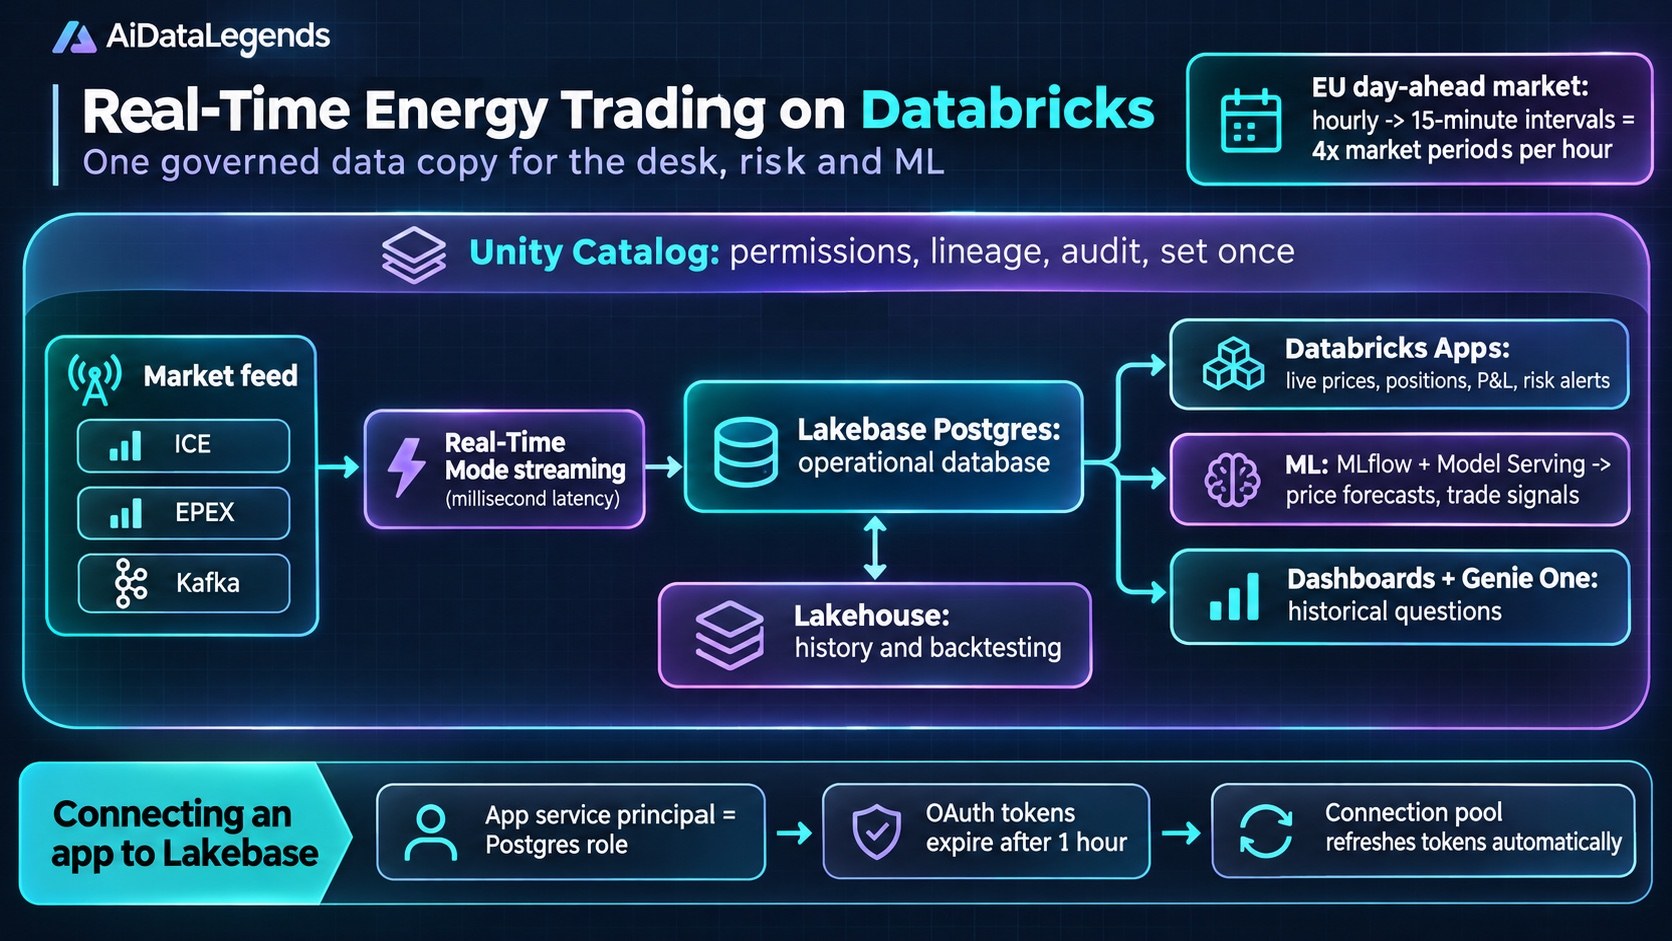
Real-Time Energy Trading on Databricks: One Governed Data Copy for the Desk, Risk and ML

Databricks streams market data with Real-Time Mode into Lakebase Postgres, serves the trading desk from it, and trains models and runs analytics on the same governed copy. Here is how the pieces fit, and how to wire an app to Lakebase.

Nov 13, 2026 · 5 min read
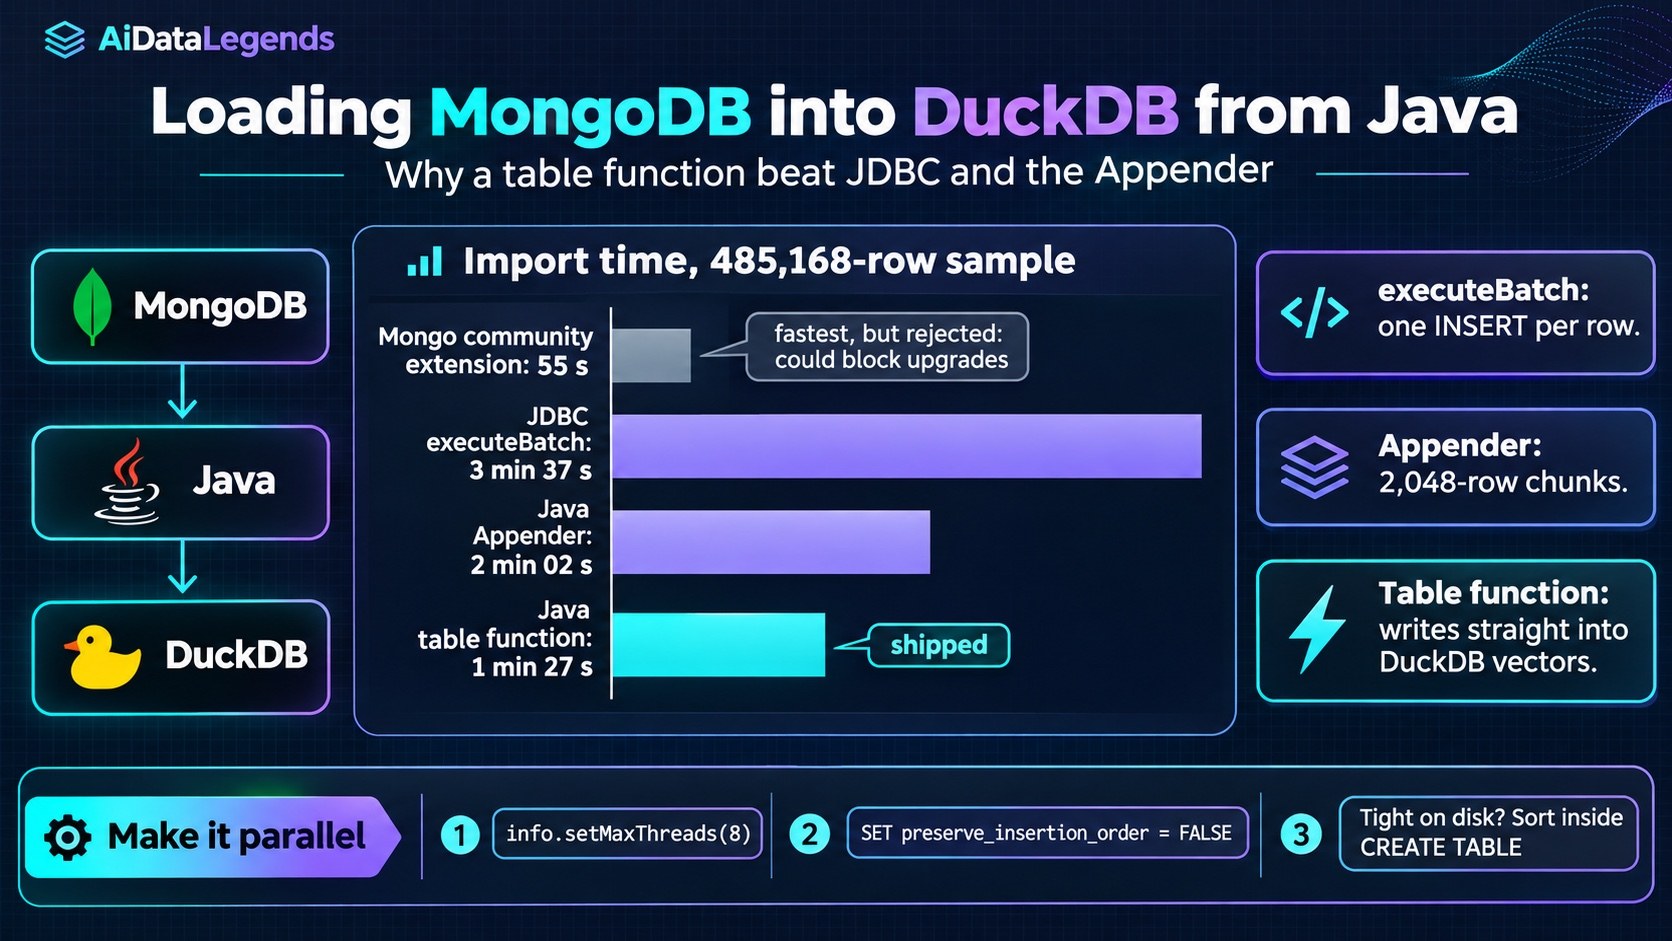
Loading MongoDB into DuckDB from Java: Why a Table Function Beat JDBC and the Appender
Data Engineering

Loading MongoDB into DuckDB from Java: Why a Table Function Beat JDBC and the Appender

On a 485,168-record sample, a pure-Java table function loaded data in 1m 27s, against 2m 02s for the Appender and 3m 37s for JDBC batches. On production data it matched the Mongo community extension.

Nov 12, 2026 · 5 min read
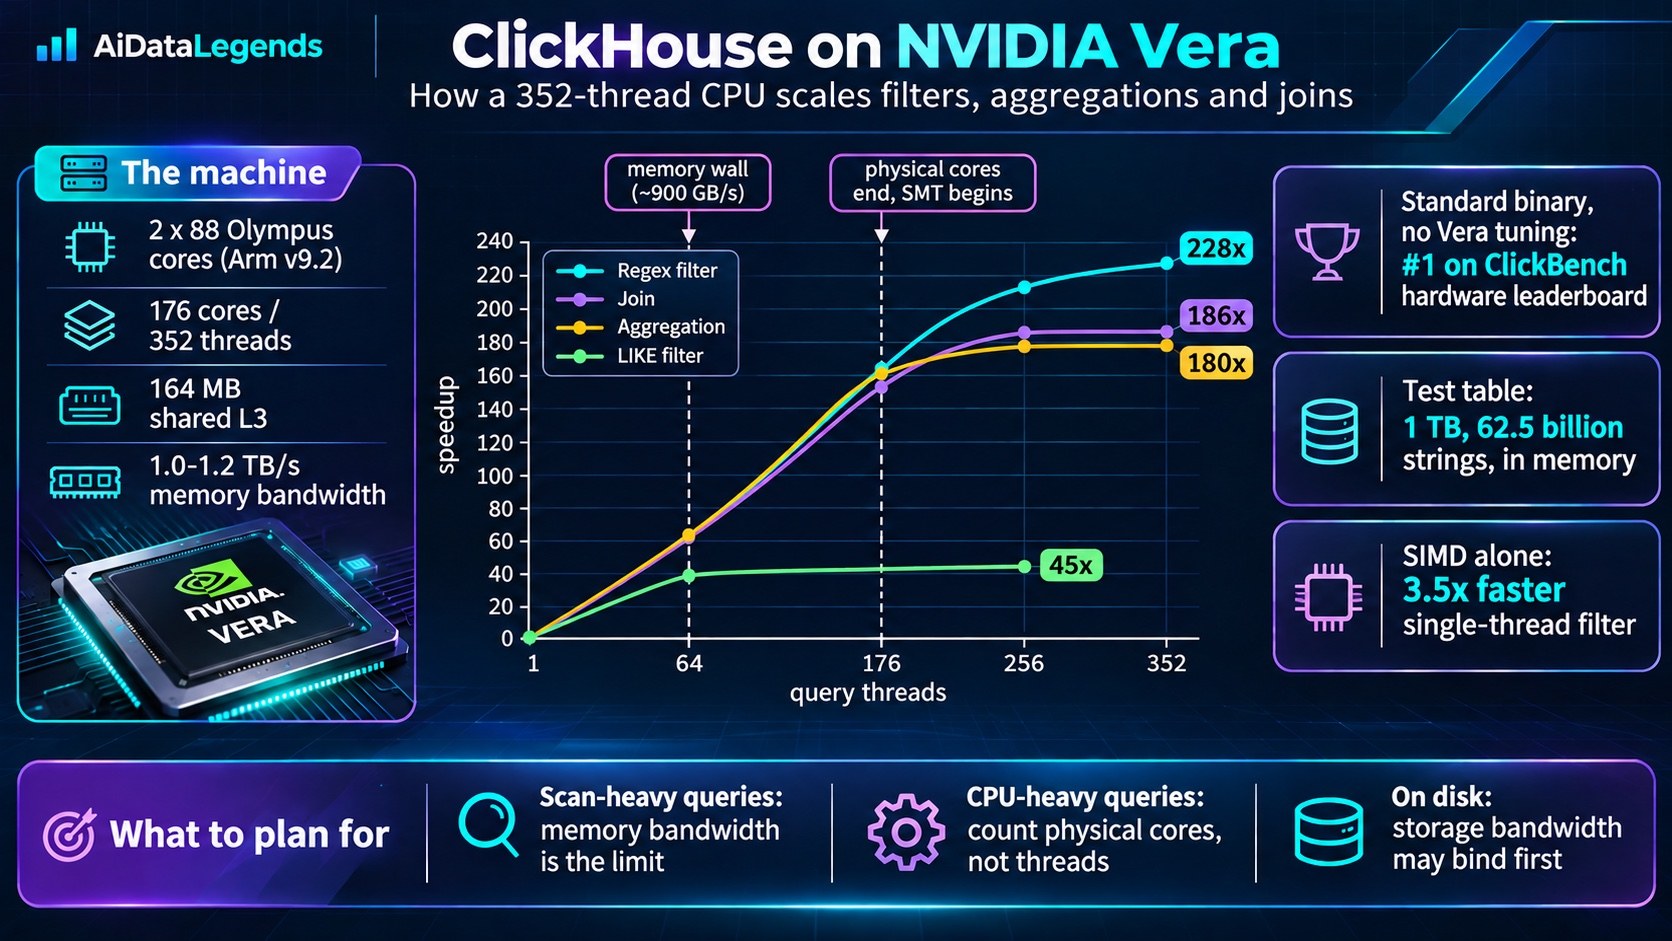
ClickHouse on NVIDIA Vera: How a 352-Thread CPU Scales Filters, Aggregations and Joins
Data Engineering

ClickHouse on NVIDIA Vera: How a 352-Thread CPU Scales Filters, Aggregations and Joins

An unmodified ClickHouse binary scales almost linearly to Vera's 176 physical cores on CPU-heavy queries. Past that, SMT adds little, and a simple LIKE filter runs out of memory bandwidth at 64 threads.

Nov 11, 2026 · 5 min read