Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler
AI Engineering

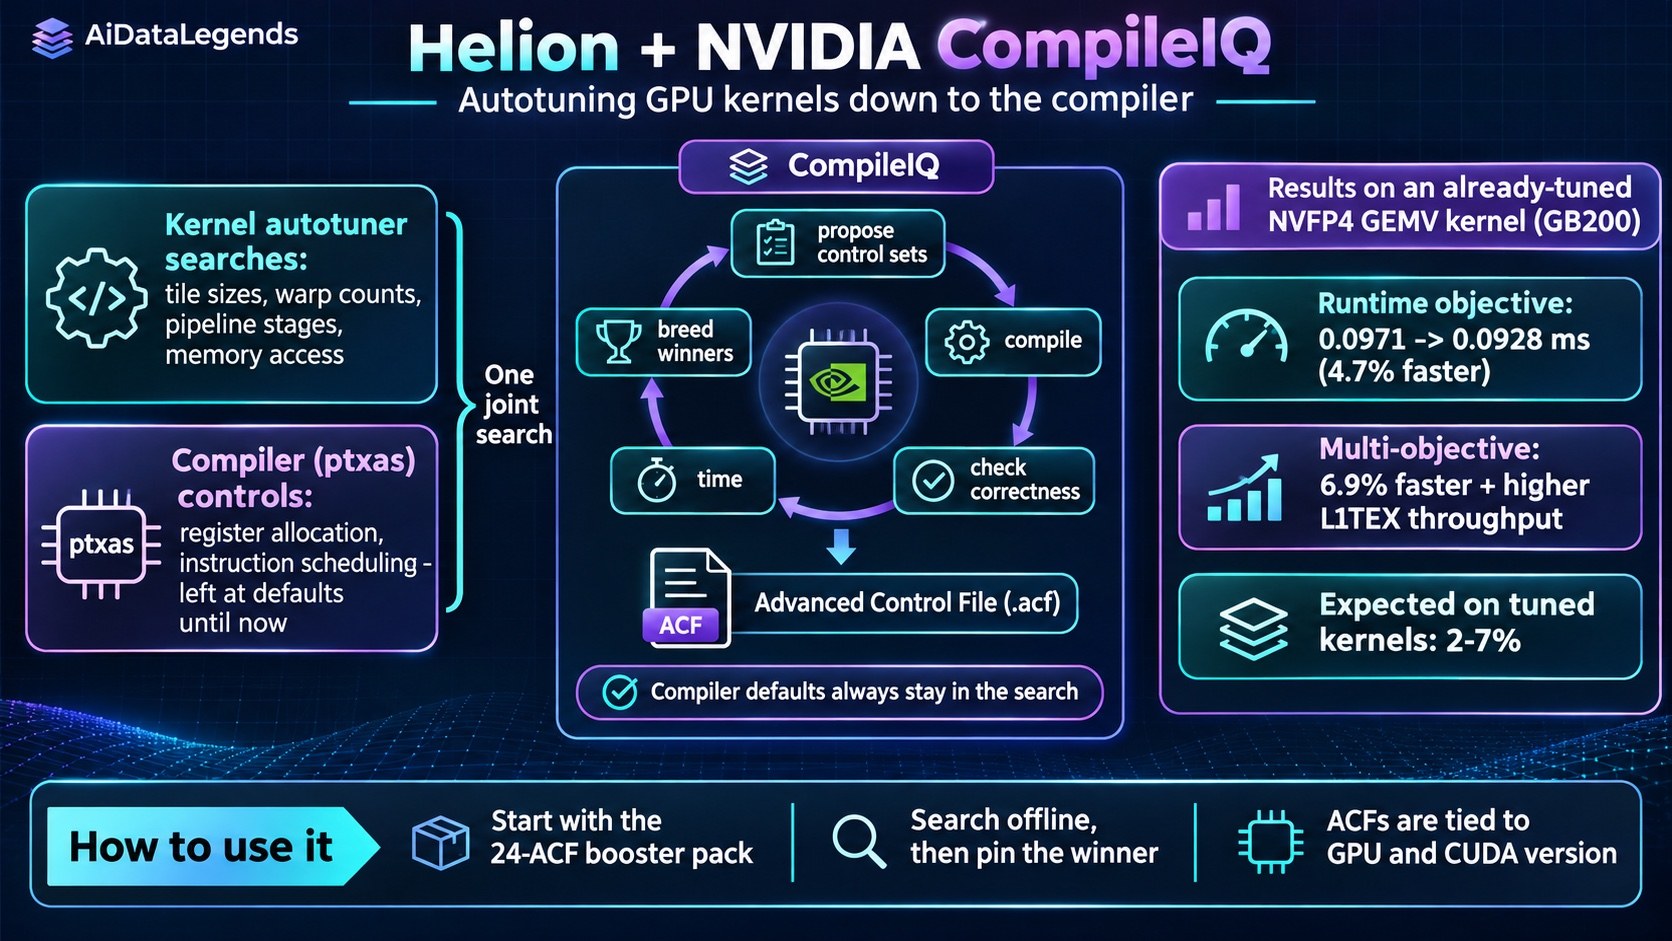
Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler

Kernel autotuners stop at tile sizes and warp counts. Helion can now search ptxas compiler controls in the same loop, using CompileIQ's Advanced Control Files, for 2 to 7% more speed on kernels already tuned.
Nov 19, 2026 · 4 min read
TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning
AI Engineering

TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning

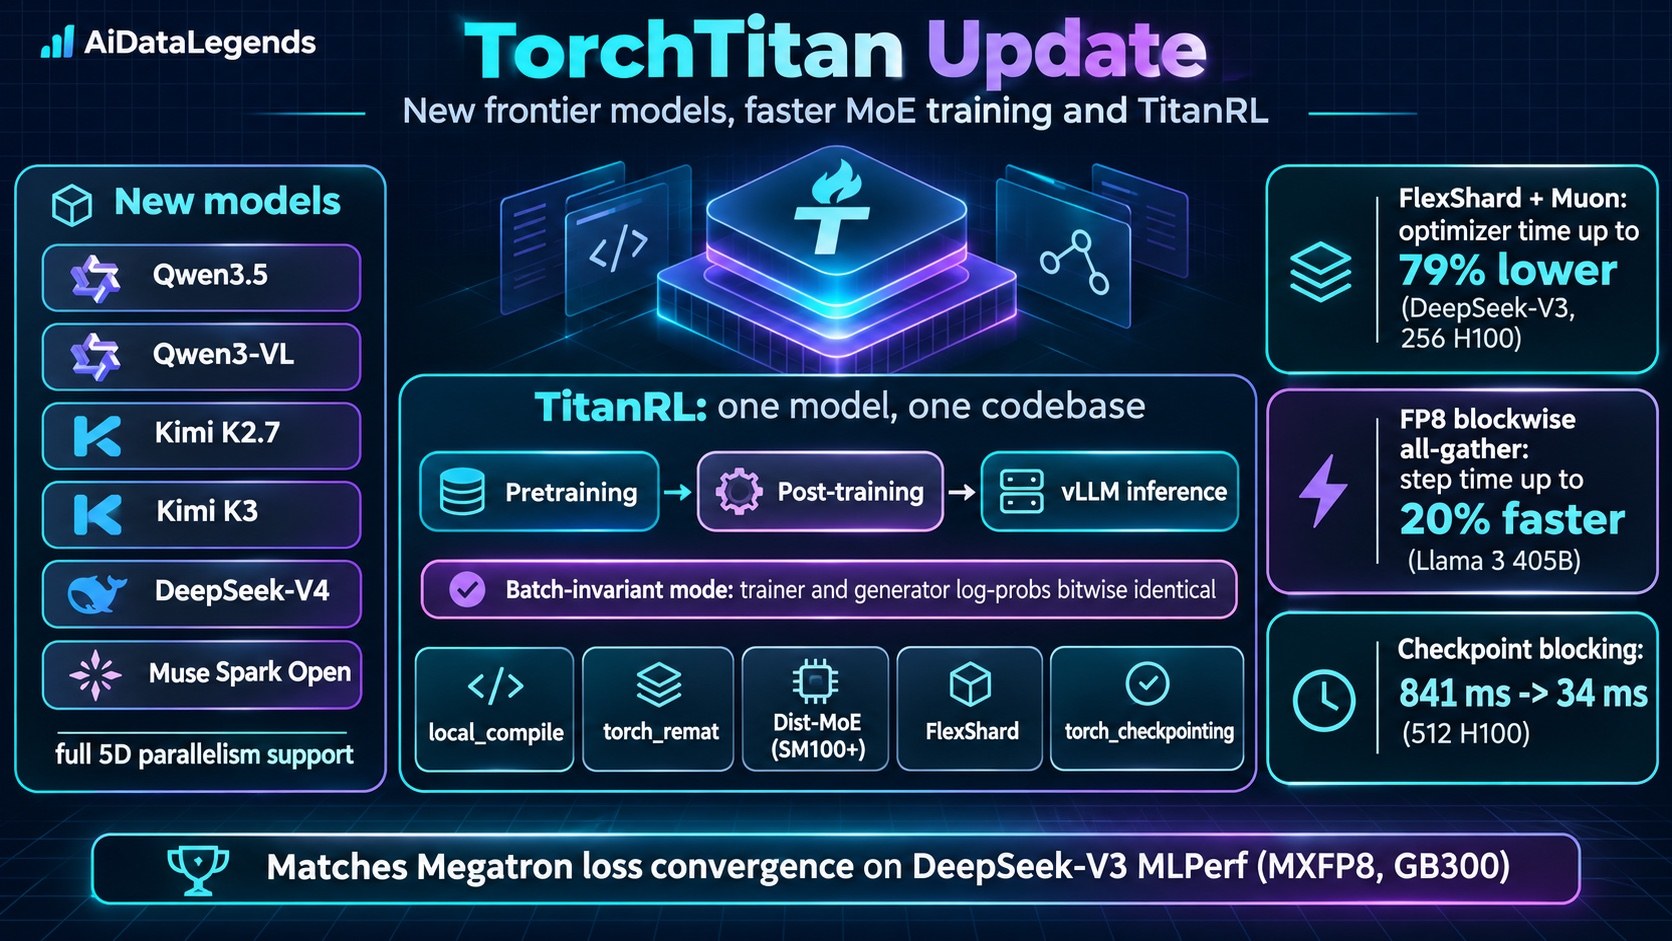
PyTorch's TorchTitan adds Qwen3.5, Kimi K3 and DeepSeek-V4, an RL stack whose trainer and generator can produce bitwise-identical log-probabilities, and FlexShard, which cut Muon optimizer time by up to 79%.

Nov 18, 2026 · 4 min read
Evaluating Multi-Agent Systems With Amazon Bedrock AgentCore: Helpfulness, Business Accuracy and Explainability
AI Engineering

Evaluating Multi-Agent Systems With Amazon Bedrock AgentCore: Helpfulness, Business Accuracy and Explainability

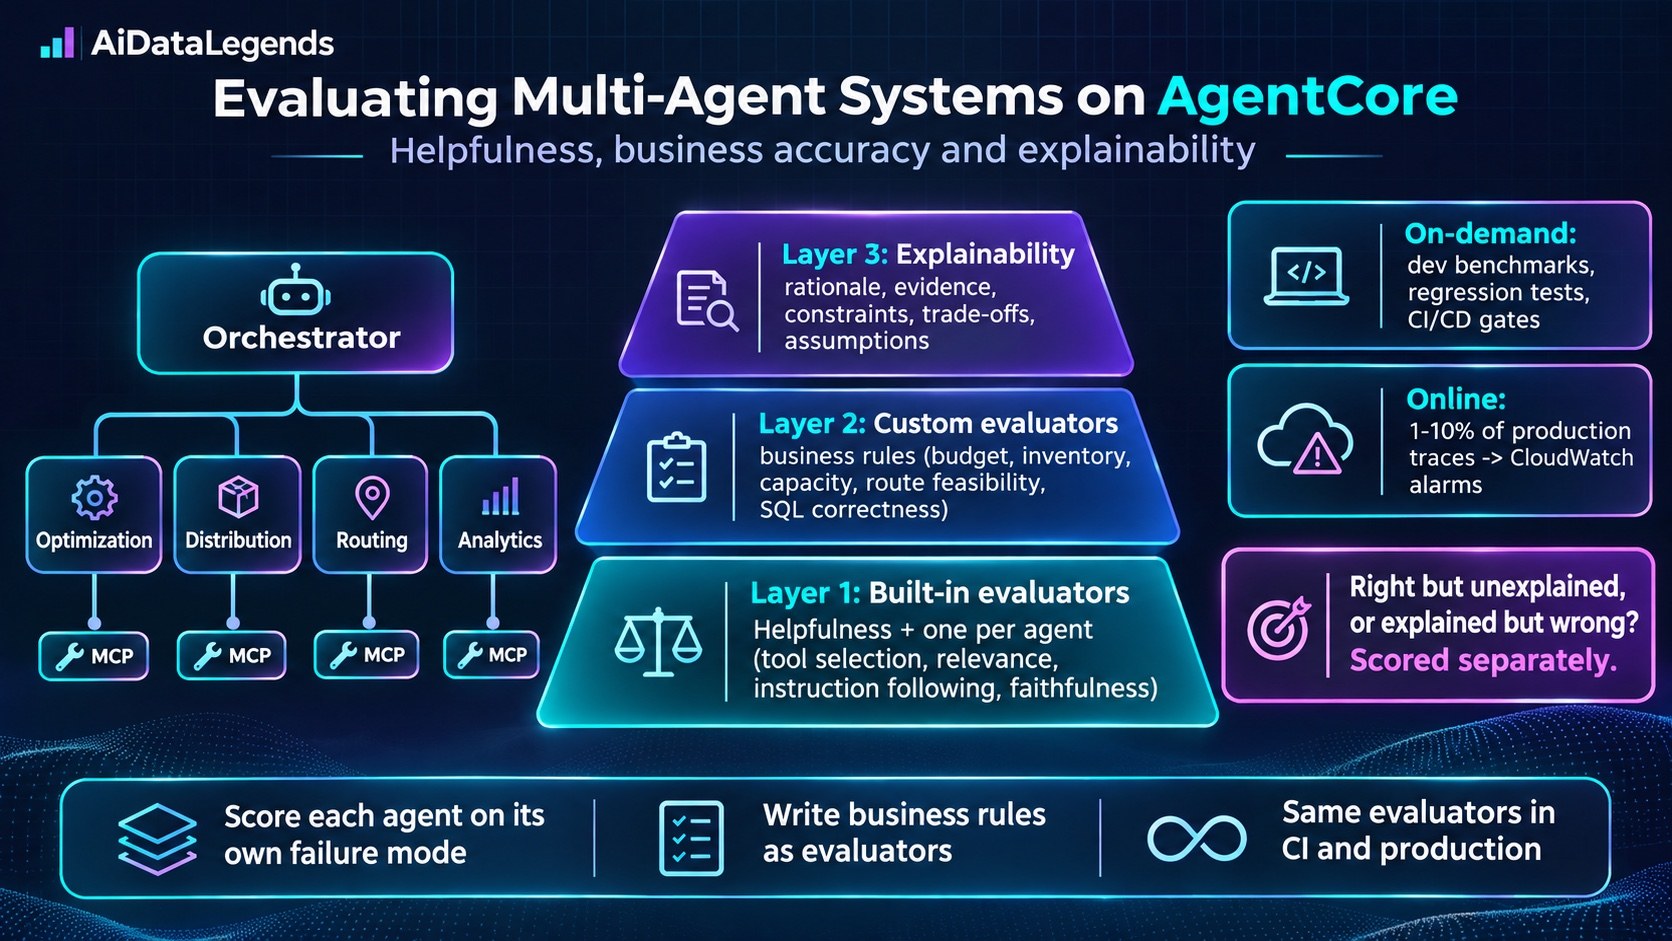
AWS shows a three-layer way to test agents on AgentCore. Built-in evaluators set a baseline, custom evaluators check business rules, and separate explainability evaluators check whether agents can say why.

Nov 16, 2026 · 5 min read
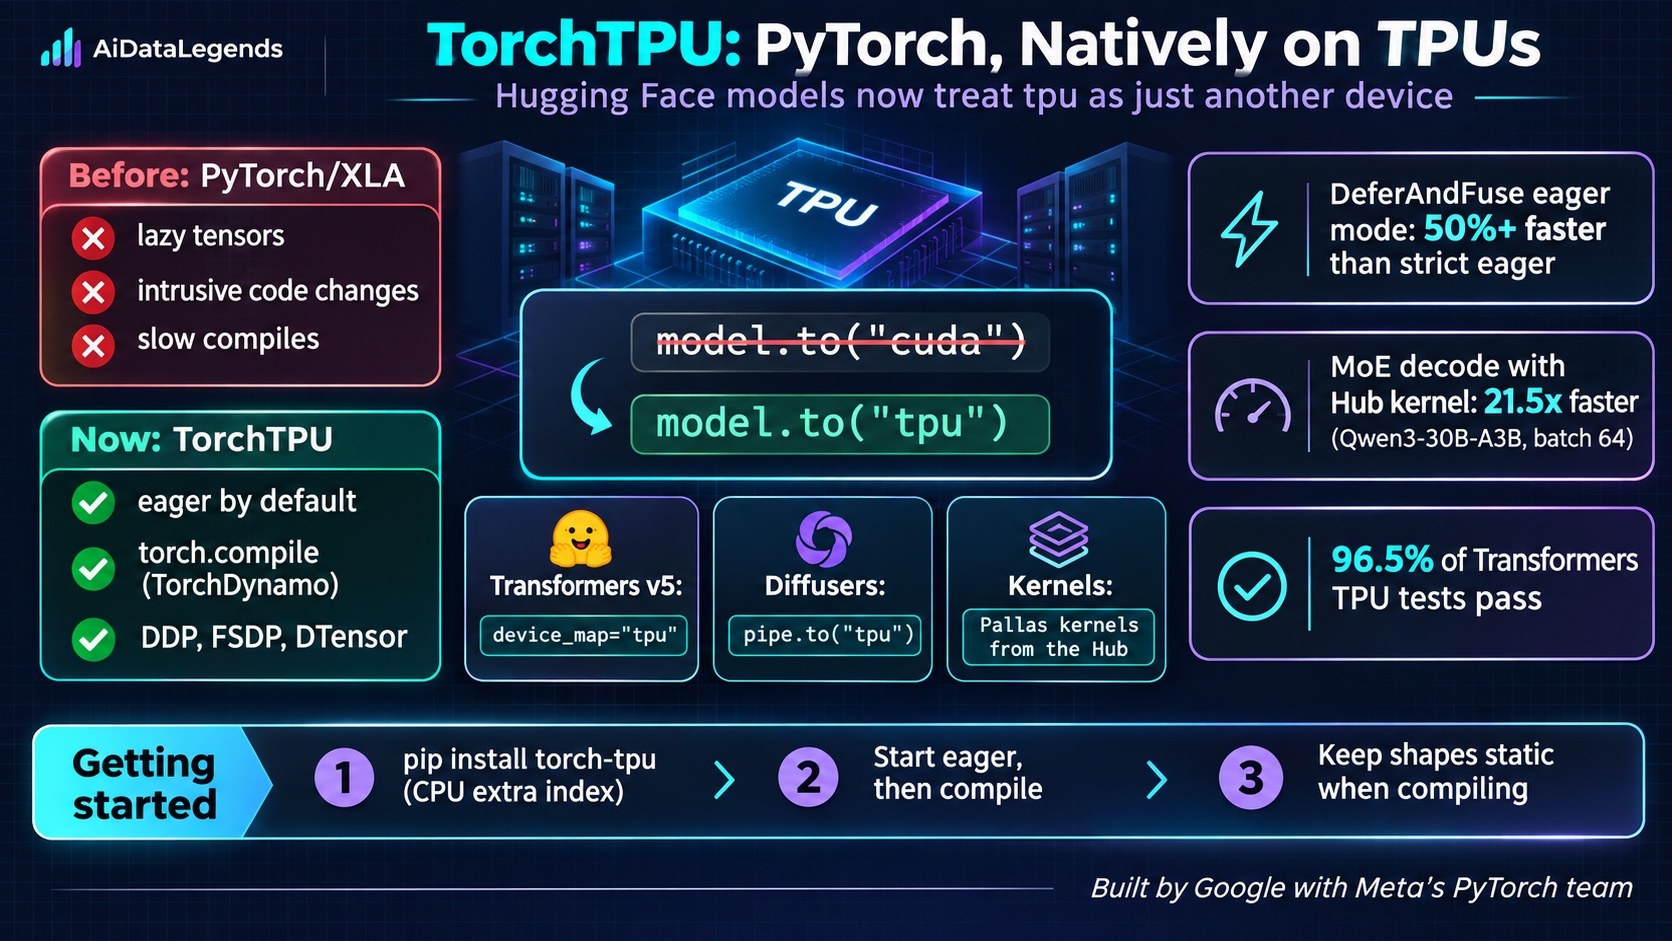
TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along
AI Engineering

TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along

Google and Meta built TorchTPU, a native PyTorch backend for TPUs with eager execution and torch.compile. Hugging Face Transformers, Diffusers and Kernels now treat "tpu" as just another device.

Nov 15, 2026 · 5 min read
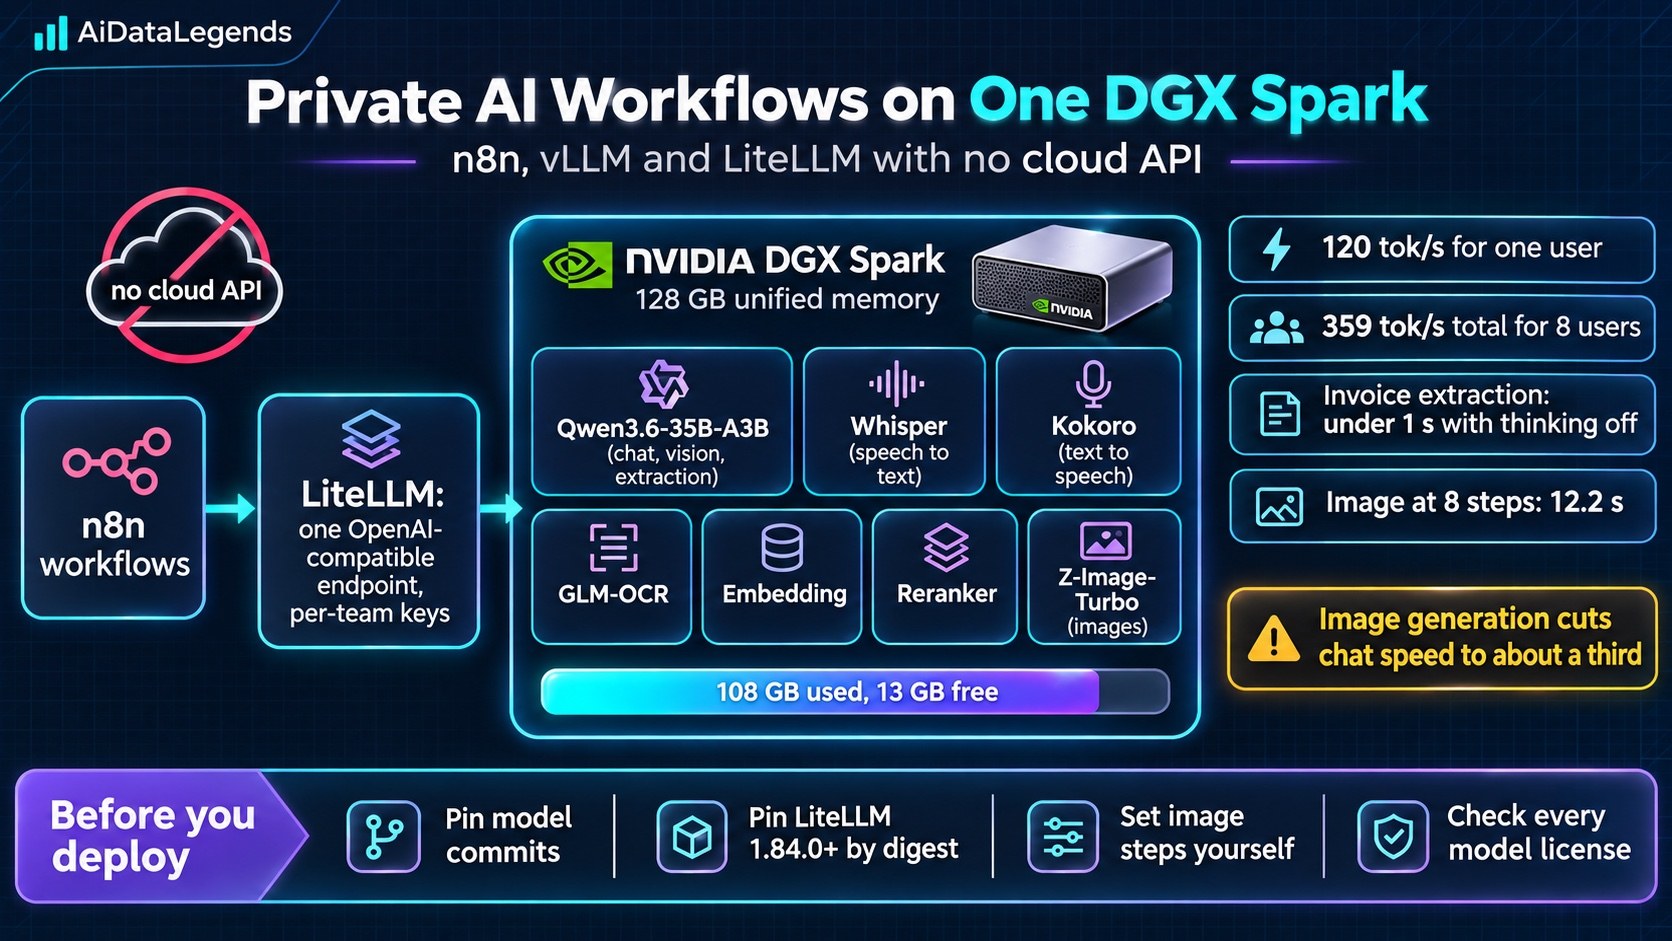
Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API
AI Engineering

Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API

n8n served seven models from one 128GB DGX Spark behind a single OpenAI-compatible endpoint. Qwen3.6-35B-A3B ran at 120 tokens per second for one user and 359 in total for eight, but image generation cut chat speed to a third.

Nov 14, 2026 · 5 min read
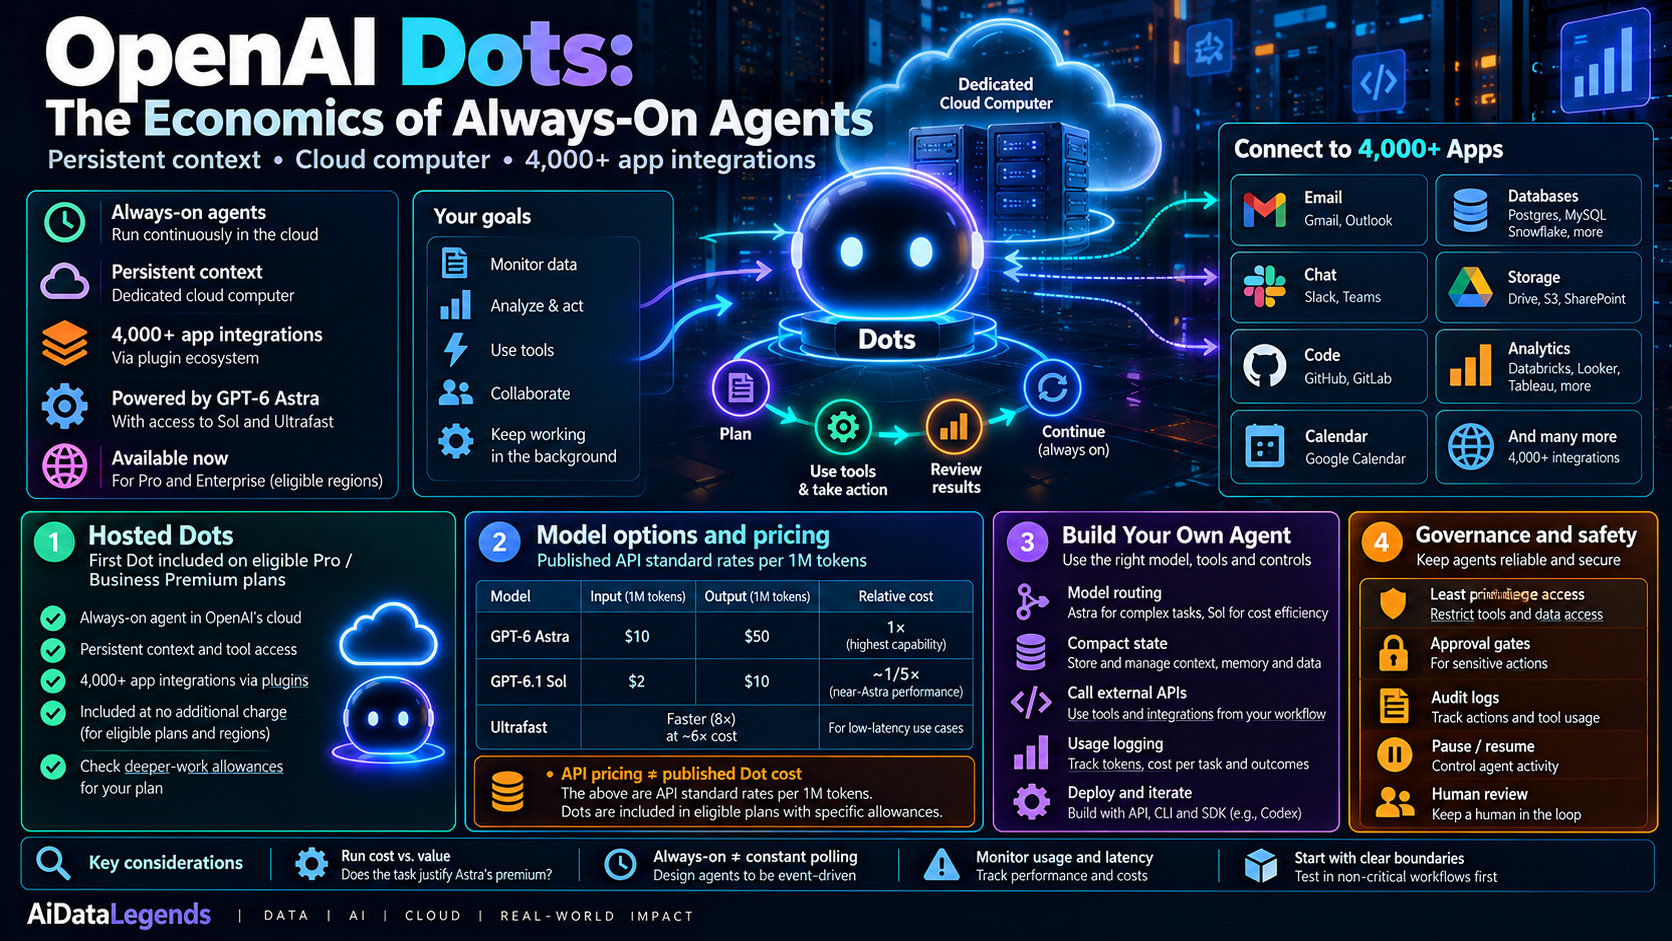
OpenAI Dots: A Persistent Cloud Agent for 4,000+ Apps
AI Engineering

OpenAI Dots: A Persistent Cloud Agent for 4,000+ Apps

Dots gives Pro and Business Premium users a dedicated cloud computer powered by GPT-6 Astra, but its high default cost makes the cheaper GPT-6.1 Sol a critical consideration for engineers.

Oct 26, 2026 · 4 min read
Google Research Proposes Contextual Integrity Policy Engines and Multi-Agent Benchmarks for Agentic Privacy
AI Engineering

Google Research Proposes Contextual Integrity Policy Engines and Multi-Agent Benchmarks for Agentic Privacy

A Google Research workshop report proposes LLM-driven policy engines based on contextual integrity, plus standardized multi-agent benchmarks, to make AI agents more privacy-aware, auditable and safer to deploy. What it means for data and AI engineers.

Oct 08, 2026 · 13 min read
GPT-6.1 Sol on Amazon Bedrock: Near-Astra performance at a fraction of the cost
AI Engineering

GPT-6.1 Sol on Amazon Bedrock: Near-Astra performance at a fraction of the cost

OpenAI's GPT-6.1 Sol brings near-Astra performance to coding, computer use and professional work at one-fifth of Astra's standard token prices. Here's what Amazon Bedrock adds, from pricing and a 1M-token context to endpoints and code.

Oct 06, 2026 · 13 min read
Grok 4.7 on Amazon Bedrock: Routing, reasoning effort, and cost with OpenAI-compatible APIs
AI Engineering

Grok 4.7 on Amazon Bedrock: Routing, reasoning effort, and cost with OpenAI-compatible APIs

xAI's Grok 4.7 is now on Amazon Bedrock with a 500K-token context window. Here's how reasoning effort, Geo vs Global routing and service tiers change cost and latency, with OpenAI-compatible code you can reuse.

Oct 05, 2026 · 9 min read