AI Engineering
Private AI Workflows on One NVIDIA DGX Spark: n8n, vLLM and LiteLLM With No Cloud API
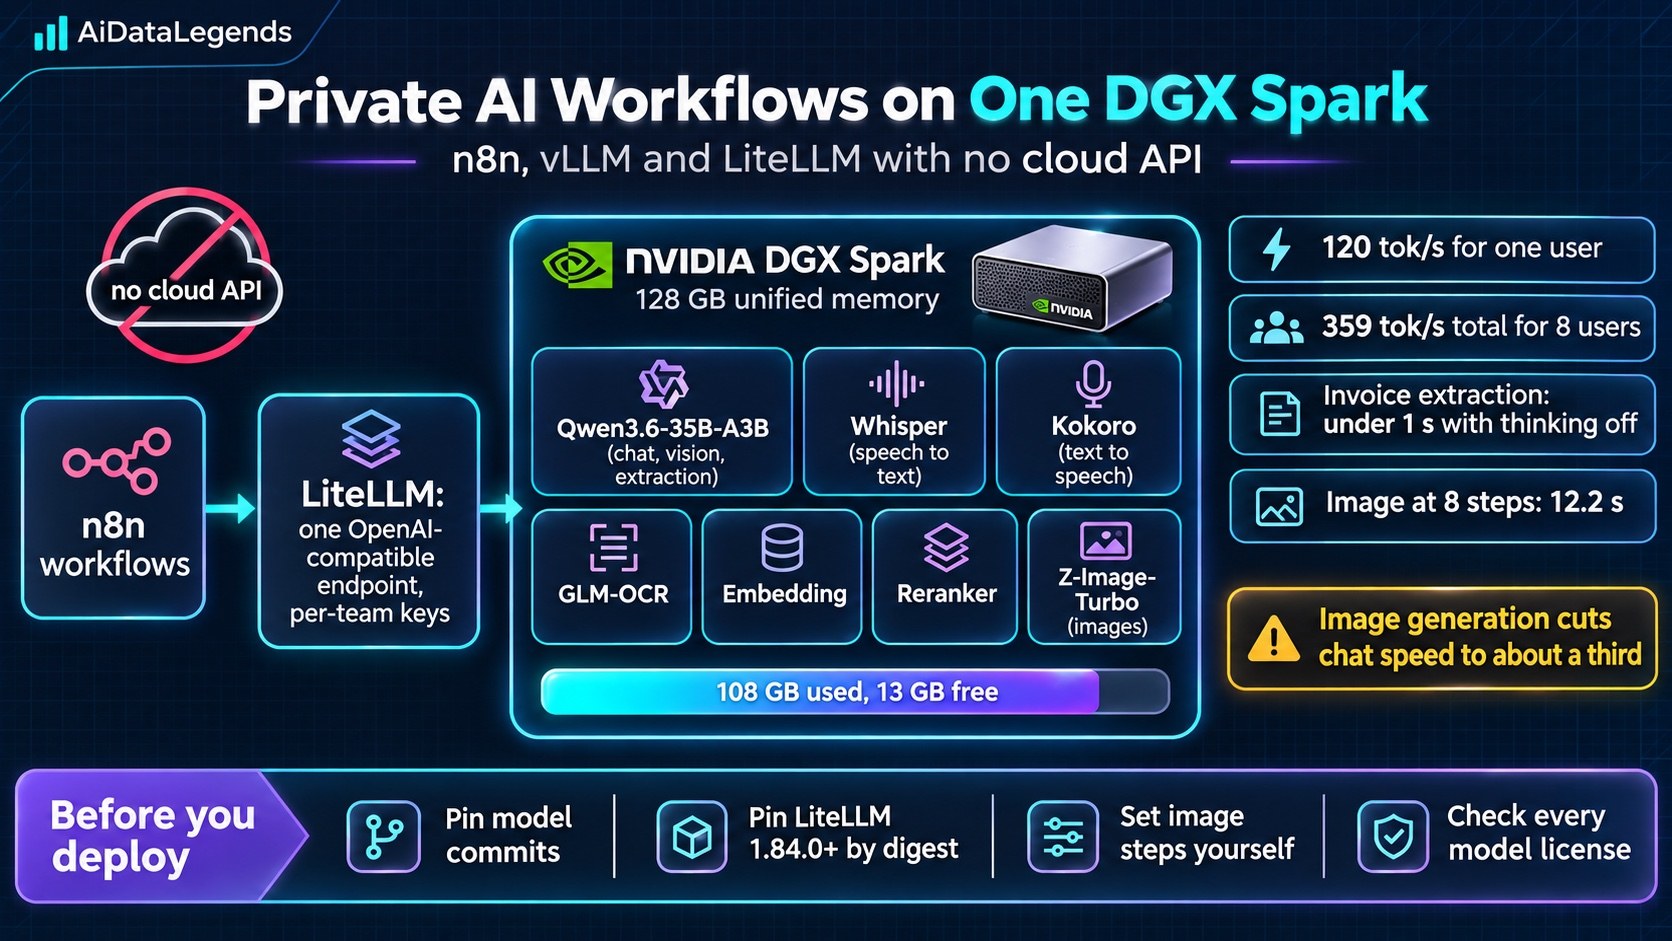
n8n served seven models from one 128GB DGX Spark behind a single OpenAI-compatible endpoint. Qwen3.6-35B-A3B ran at 120 tokens per second for one user and 359 in total for eight, but image generation cut chat speed to a third.
