Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler
AI Engineering

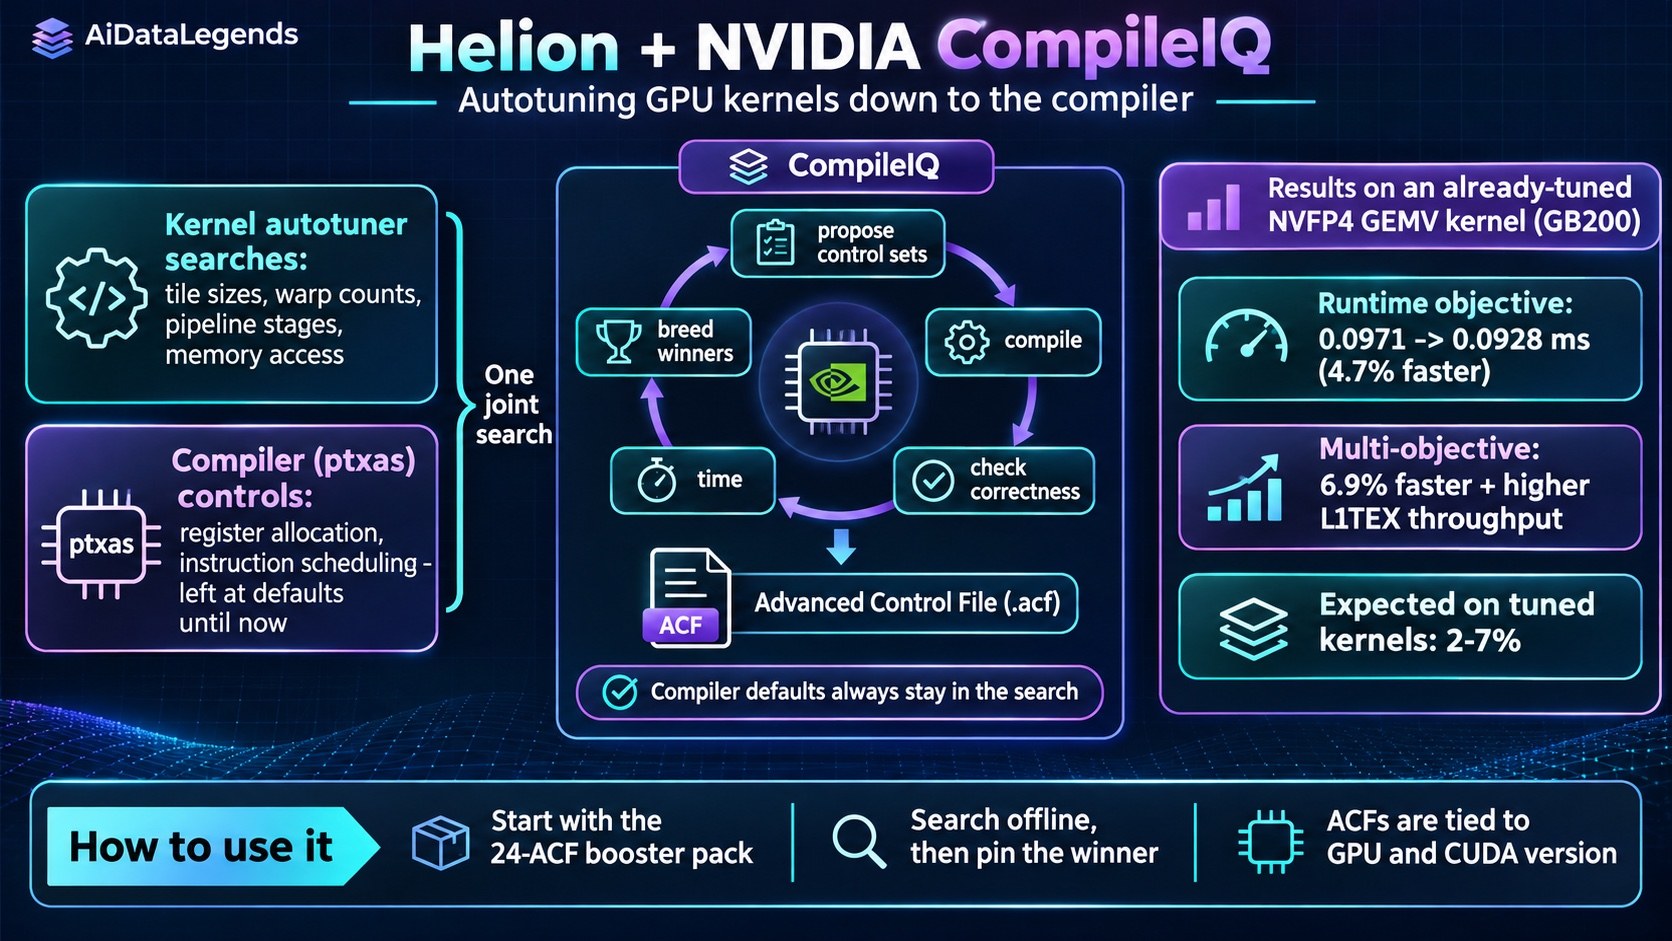
Helion and NVIDIA CompileIQ: Autotuning GPU Kernels Down to the Compiler

Kernel autotuners stop at tile sizes and warp counts. Helion can now search ptxas compiler controls in the same loop, using CompileIQ's Advanced Control Files, for 2 to 7% more speed on kernels already tuned.
Nov 19, 2026 · 4 min read
TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning
AI Engineering

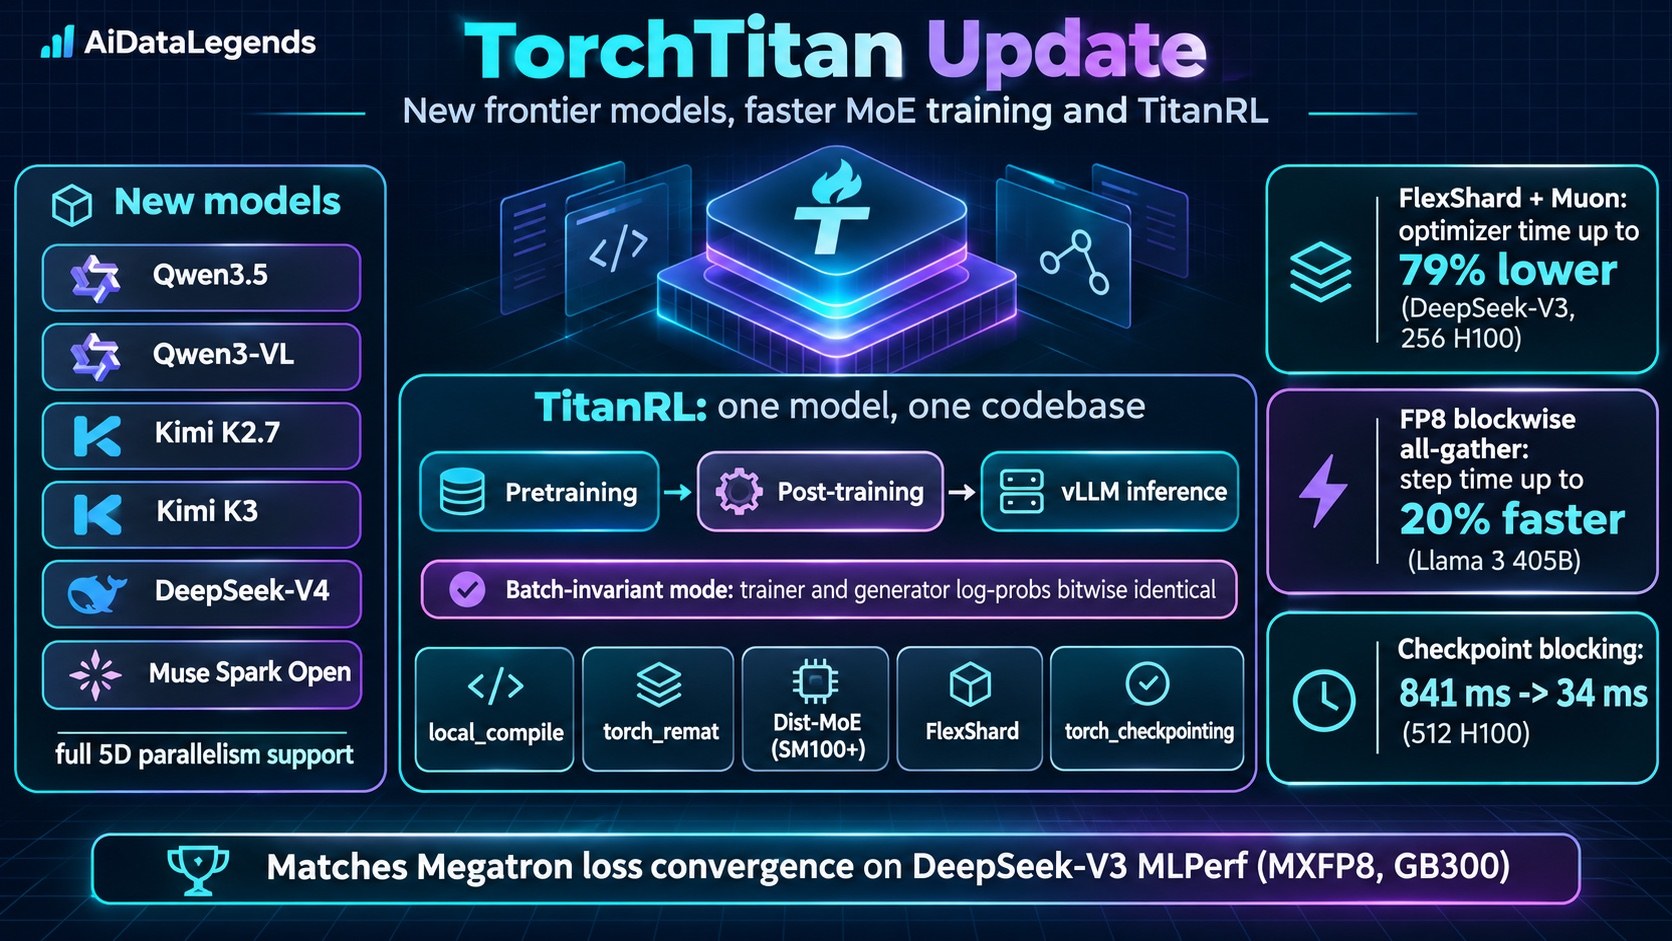
TorchTitan Update: New Frontier Models, Faster MoE Training and TitanRL for Reinforcement Learning

PyTorch's TorchTitan adds Qwen3.5, Kimi K3 and DeepSeek-V4, an RL stack whose trainer and generator can produce bitwise-identical log-probabilities, and FlexShard, which cut Muon optimizer time by up to 79%.

Nov 18, 2026 · 4 min read
TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along
AI Engineering

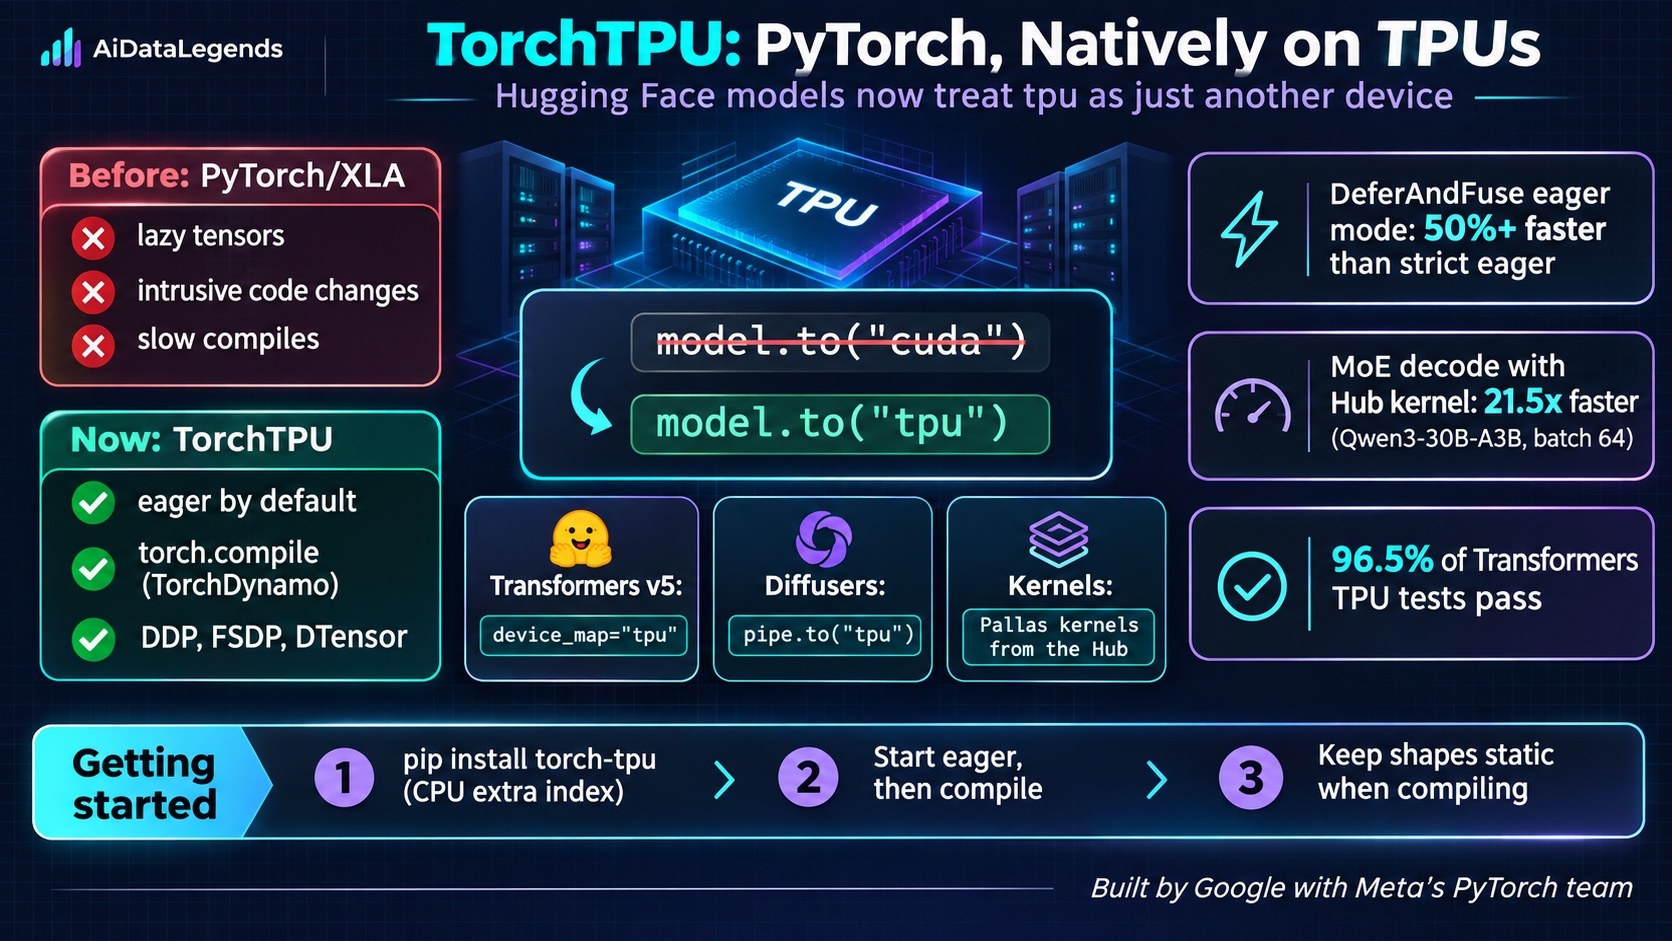
TorchTPU: PyTorch Runs Natively on Google TPUs, and Hugging Face Models Come Along

Google and Meta built TorchTPU, a native PyTorch backend for TPUs with eager execution and torch.compile. Hugging Face Transformers, Diffusers and Kernels now treat "tpu" as just another device.

Nov 15, 2026 · 5 min read